---
title: MiniCPM-OCR-1.0-AWQ
canonical_url: "https://www.modelscope.ai/models/OpenBMB/MiniCPM-OCR-1.0-AWQ"
md_url: "https://www.modelscope.ai/models/OpenBMB/MiniCPM-OCR-1.0-AWQ.md"
repository: OpenBMB/MiniCPM-OCR-1.0-AWQ
last_updated: 2026-11-10
license: apache-2.0
pipeline_tag: image-text-to-text
tasks:
  - image-text-to-text
model_type:
  - minicpm_ocr
architectures:
  - MiniCPMOcrForConditionalGeneration
base_model:
  - openbmb/MiniCPM-OCR-1.0
base_model_relation: quantized
parameters: 1.3B
tensor_type:
  - F16
  - BF16
  - I32
library_name:
  - safetensors
  - pytorch
frameworks:
  - pytorch
language:
  - en
  - zh
downloads: 34
stars: 0
tags:
  - minicpm-ocr
  - ocr
  - document-parsing
  - multimodal
  - awq
  - 4-bit
  - quantized
---

# MiniCPM-OCR-1.0-AWQ

> MiniCPM-OCR-1.0-AWQ - An open-source model by OpenBMB on ModelScope. 🚀 Free API Try it online for free, then call the API from your own code. Playground ( CN / Global ) API docs ( CN / Global ) 🤖 Agent Skill One prompt: the agent installs it and parses…

OpenBMB/MiniCPM-OCR-1.0-AWQ is a 1.3B-parameter image-text-to-text model on ModelScope. licensed under apache-2.0. derived from openbmb/MiniCPM-OCR-1.0.

- **Repository**: OpenBMB/MiniCPM-OCR-1.0-AWQ
- **License**: apache-2.0
- **Tasks**: image-text-to-text
- **Parameters**: 1.3B
- **Base model**: openbmb/MiniCPM-OCR-1.0
- **Tags**: minicpm-ocr, ocr, document-parsing, multimodal, awq, 4-bit, quantized
- **Downloads**: 34
- **Stars**: 0
- **Last updated**: 2026-11-10

Source: https://www.modelscope.ai/models/OpenBMB/MiniCPM-OCR-1.0-AWQ

---

<div align="center">

<p align="center">
  <a href="https://github.com/OpenBMB/MiniCPM"><img src="https://raw.githubusercontent.com/OpenBMB/MiniCPM-OCR/main/assets/minicpm-ocr/minicpm-logo.jpg" width="300" alt="MiniCPM logo"></a>
</p>

<p align="center">
  <b>Usage Guide</b>
</p>

<table align="center" width="100%">
  <tr>
    <td align="center" width="25%" valign="top">
      <b>🚀 Free API</b><br/>
      <sub>Try it online for free, then call the API from your own code.</sub><br/>
      Playground (<a href="https://platform.modelbest.cn/console/playground/document-parse">CN</a> /
      <a href="https://platform.modelbest.ai/console/playground/document-parse">Global</a>)<br/>
      API docs (<a href="https://platform.modelbest.cn/console/docs/api/document-parse">CN</a> /
      <a href="https://platform.modelbest.ai/console/docs/api/document-parse">Global</a>)
    </td>
    <td align="center" width="25%" valign="top">
      <b>🤖 Agent Skill</b><br/>
      <sub>One prompt: the agent installs it and parses your first document.</sub><br/>
      <a href="https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/SKILL_en.md">SKILL.md</a>
    </td>
    <td align="center" width="25%" valign="top">
      <b>💻 Self-hosting</b><br/>
      <sub>vLLM / SGLang / llama.cpp / Ollama, plus an official Docker image. Data stays on your side.</sub><br/>
      <a href="https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/minicpm_ocr_tutorial_en.md">Deployment guide</a>
    </td>
    <td align="center" width="25%" valign="top">
      <b>📱 Mobile App</b><br/>
      <sub>On-device and offline. Document parsing is iOS-only for now.</sub><br/>
      <a href="https://github.com/OpenBMB/MiniCPM-V-Apps/blob/main/README.md#11-ios-demo">iOS Demo</a>
    </td>
  </tr>
</table>

<p align="center">
  Demo (<a href="https://platform.modelbest.cn/console/playground/document-parse">CN</a> /
  <a href="https://platform.modelbest.ai/console/playground/document-parse">Global</a>) &nbsp;·&nbsp;
  <a href="https://github.com/OpenBMB/MiniCPM-OCR">GitHub</a> &nbsp;·&nbsp;
  <a href="#use-with-the-minicpm-ocr-sdk">SDK usage</a> &nbsp;·&nbsp;
  <a href="https://huggingface.co/openbmb/MiniCPM-OCR-1.0-DSpark">DSpark</a> &nbsp;·&nbsp;
  <a href="https://discord.gg/JE8KQqtdn">Discord</a>
  &nbsp;|&nbsp; <a href="https://huggingface.co/openbmb/MiniCPM-OCR-1.0-AWQ/blob/main/README_zh.md">中文</a>
</p>

</div>

> **This repository hosts the AWQ W4A16 quantized version of
> [MiniCPM-OCR 1.0](https://huggingface.co/openbmb/MiniCPM-OCR-1.0).** For the original BF16 weights and the base model
> card, see [openbmb/MiniCPM-OCR-1.0](https://huggingface.co/openbmb/MiniCPM-OCR-1.0). Everything below describes the model
> itself; see [Quantization](#quantization) for what changed.
**MiniCPM-OCR 1.0** (1.3B) is the first OCR-specific model in the
[MiniCPM-V/o](https://github.com/openbmb/MiniCPM-V) family. It focuses on text-centric document
understanding — text, tables, formulas, charts, seals, and structured information extraction —
and balances quality against speed on real-world captures.

## Highlights

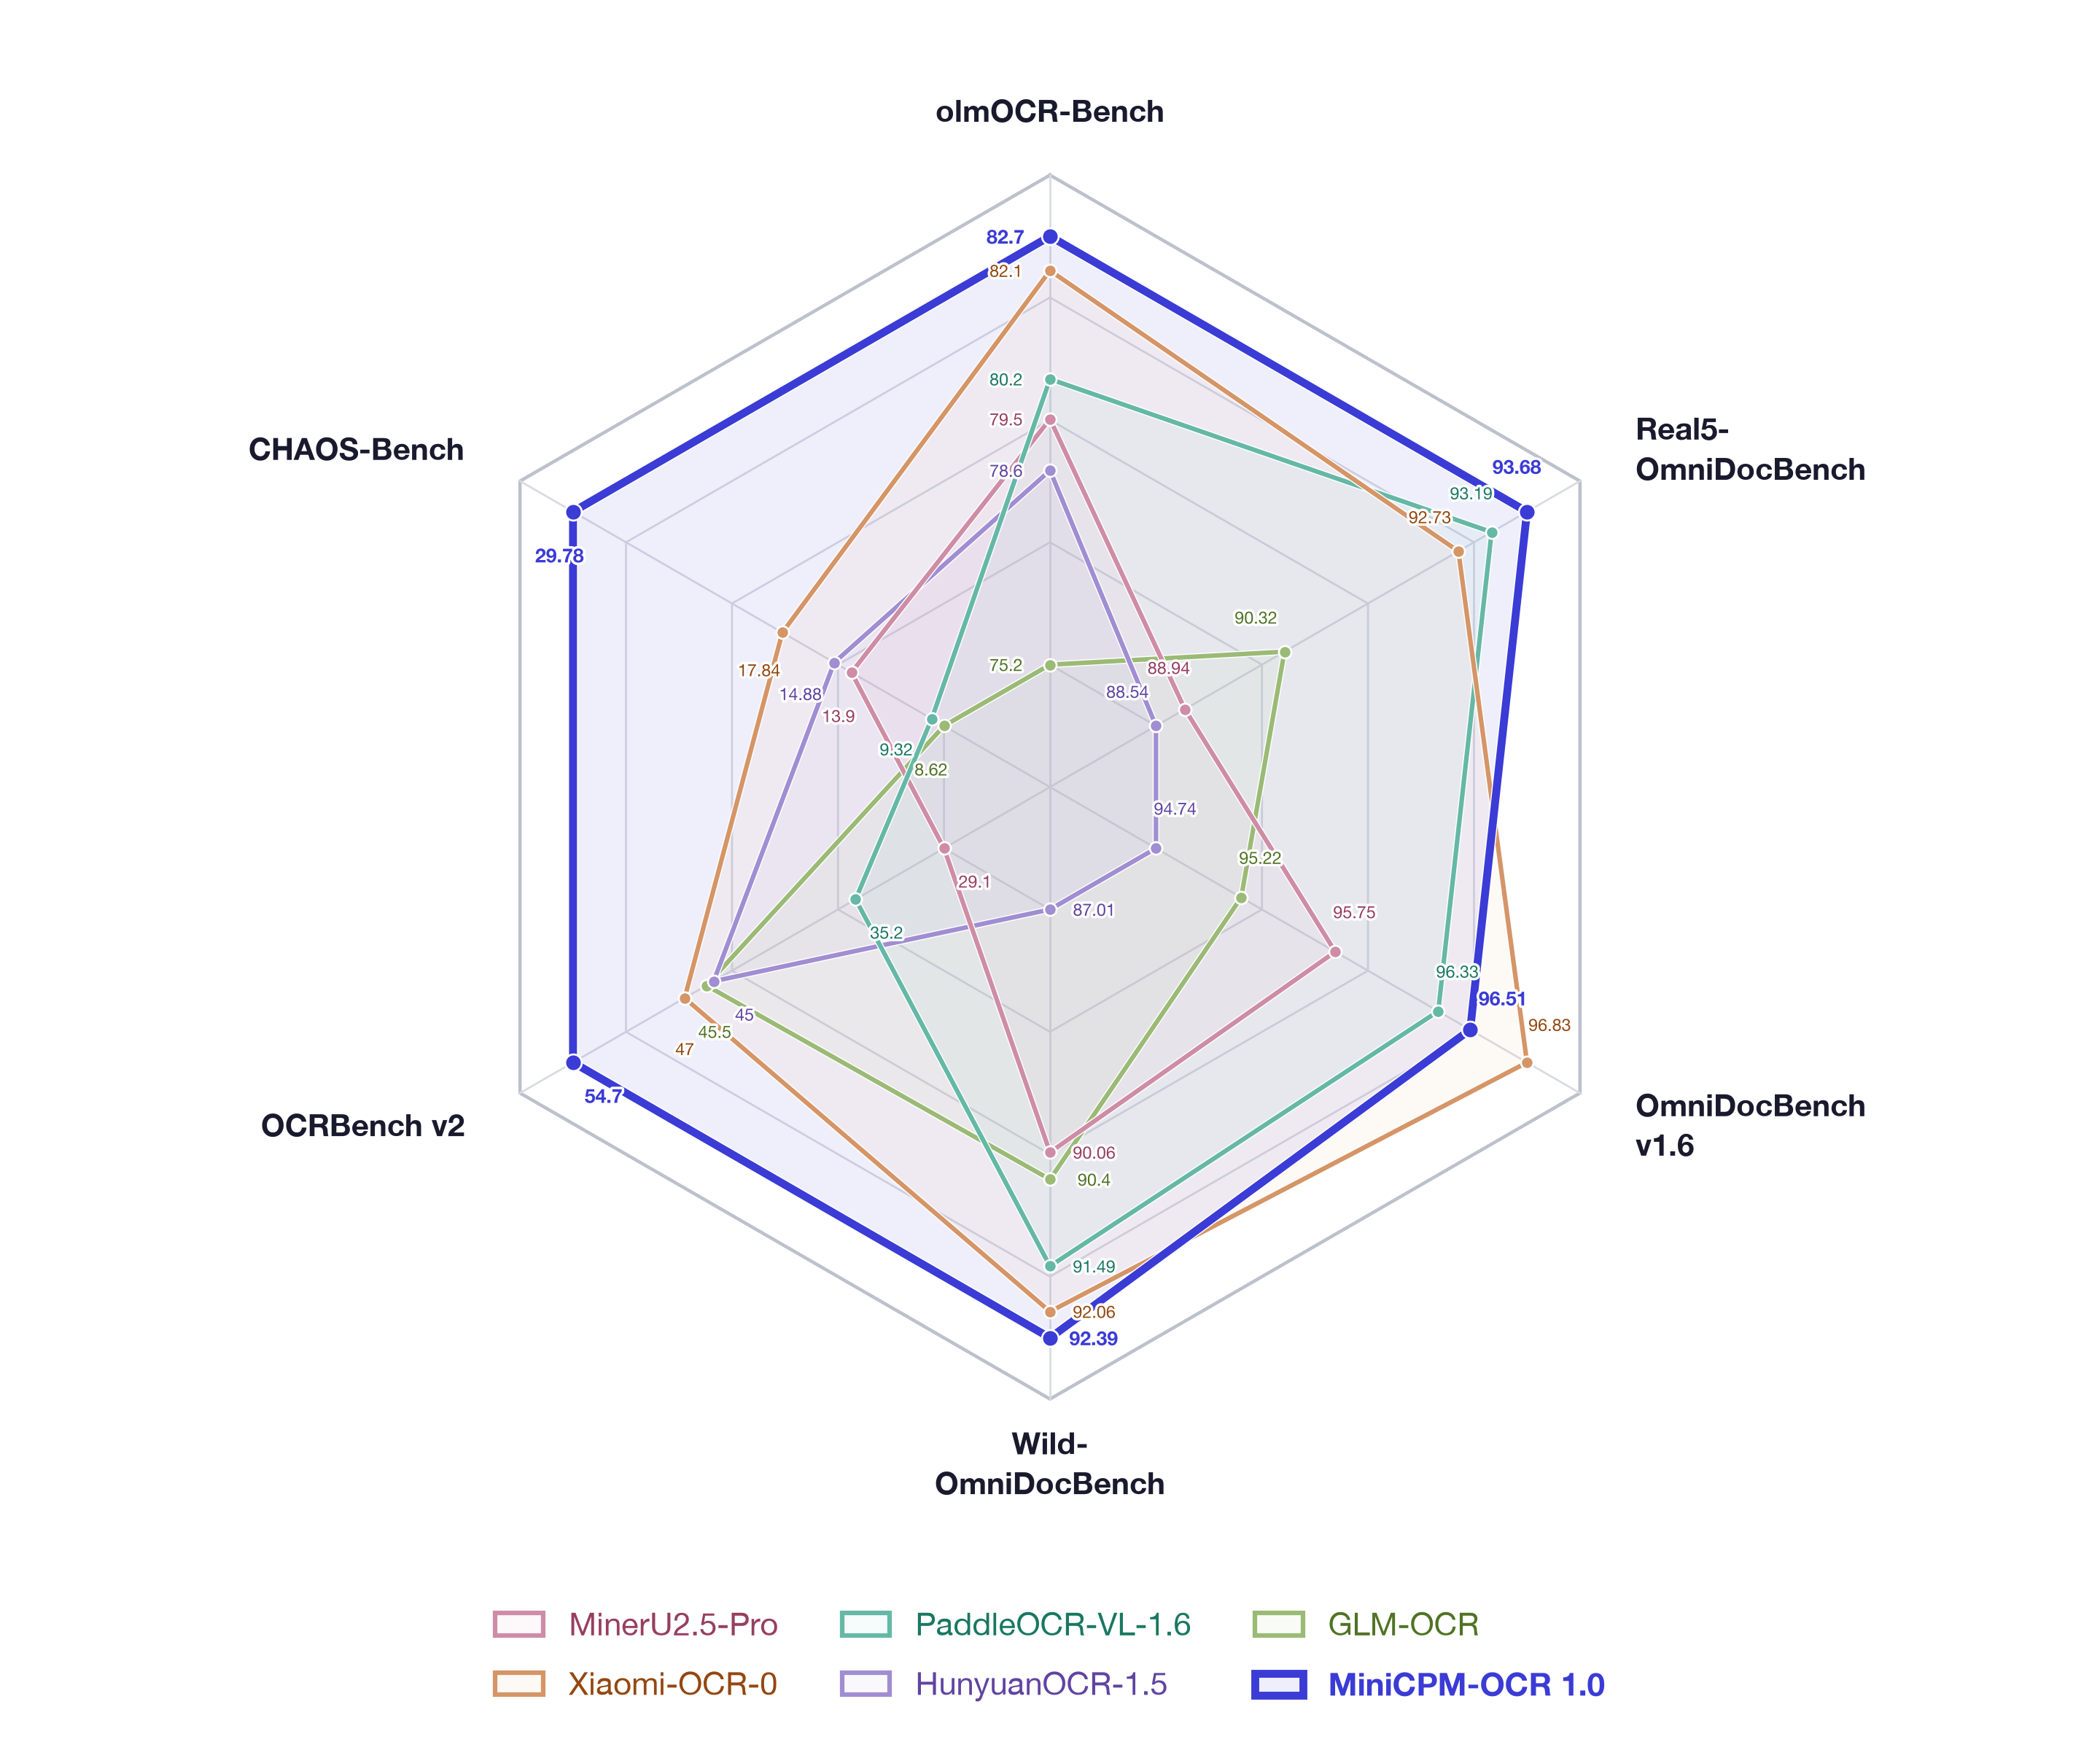
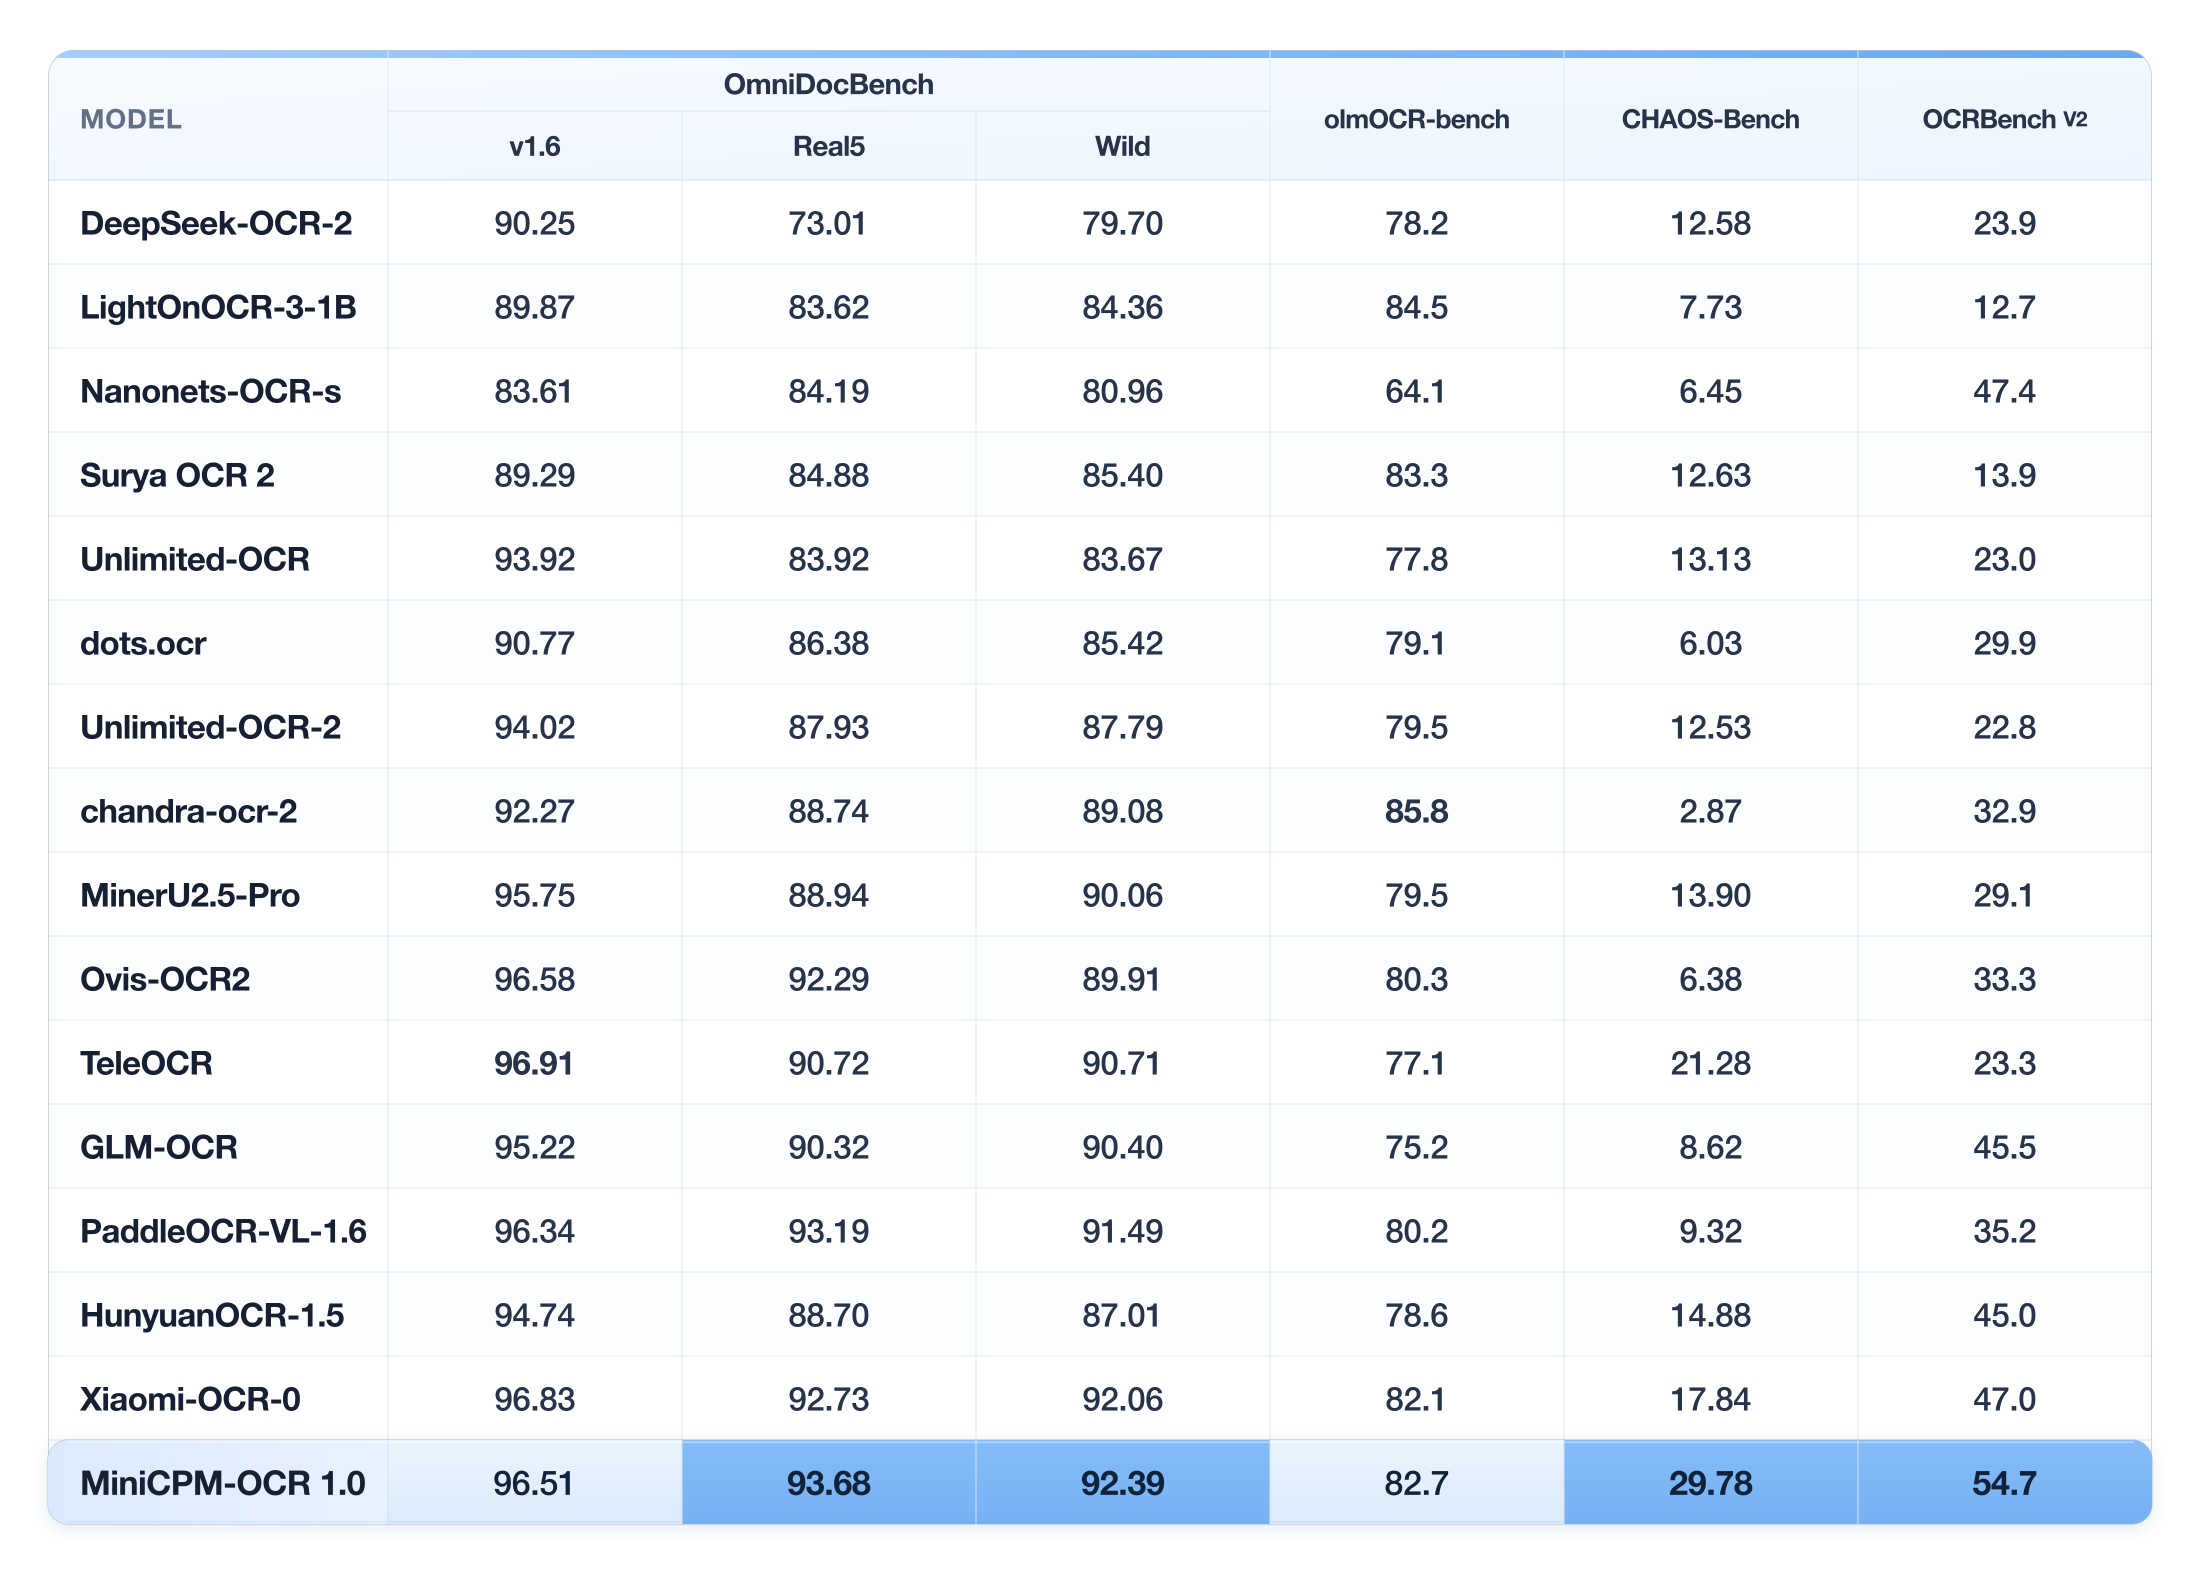
- 🏆 **SOTA document parsing**: **93.68 on Real5-OmniDocBench**, a benchmark for real-world
  document parsing, with leading results on OmniDocBench v1.6, Wild-OmniDocBench, and
  olmOCR-Bench. Handles Chinese and English documents and PDFs, including scans, curved pages,
  photographs, skewed pages, and recaptured documents.
- ⚡ **Efficient inference.** With DSpark decoding acceleration
  ([BF16](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-DSpark), [GGUF](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-DSpark-gguf)) end-to-end
  processing efficiency improves by **55%**. Throughput is about **1.49×** PaddleOCR-VL-1.6 and
  **3.62×** MinerU2.5 Pro.
- 🔍 **General recognition and information extraction**: **54.7 on OCRBench v2**, plus key
  information extraction (KIE) for downstream automation.
- 🛠️ **Easy to deploy and develop**: **vLLM, SGLang, llama.cpp, and Ollama from day one**, with
  quantized variants and multi-chip builds. Supports further fine-tuning, and ships a pip SDK,
  a full API, and agent workflows. Online demos: [China](https://platform.modelbest.cn/console/playground/document-parse) ·
  [Global](https://platform.modelbest.ai/console/playground/document-parse).

## SOTA quality at higher throughput

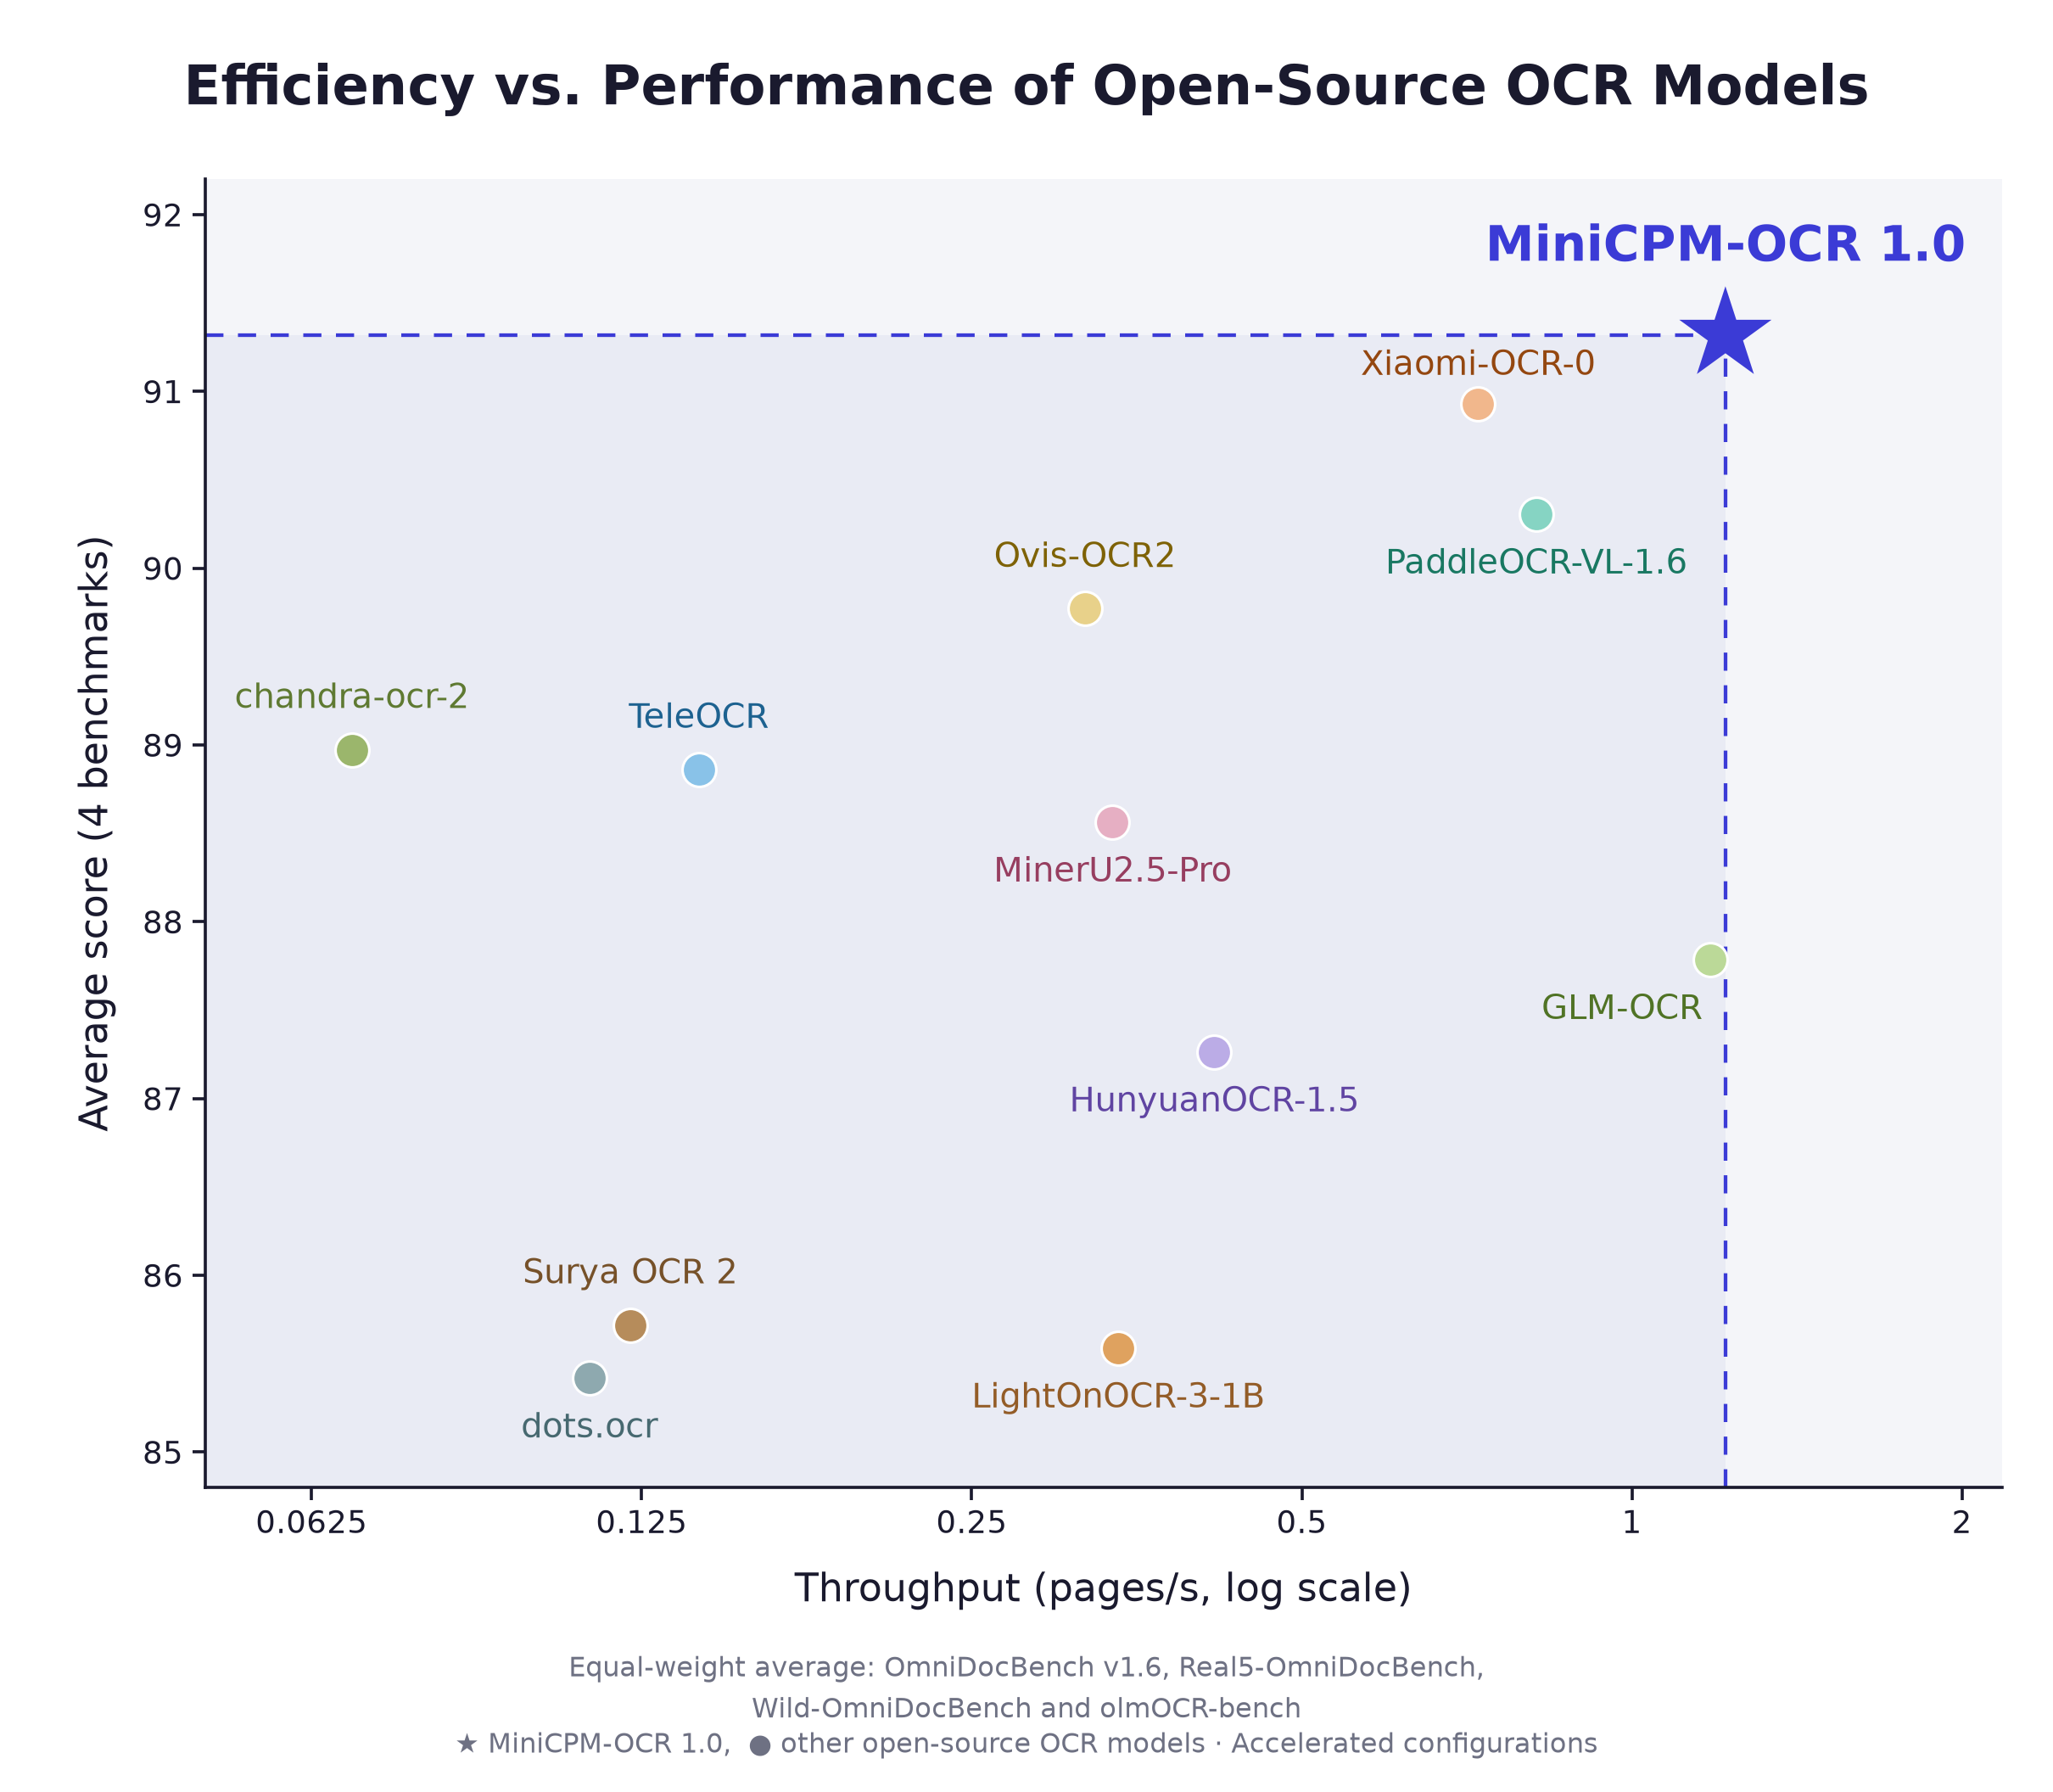
Among the open-source OCR models compared, MiniCPM-OCR 1.0 reaches **1.2 pages/s** and the
highest equal-weight average score across OmniDocBench v1.6, Real5-OmniDocBench,
Wild-OmniDocBench, and olmOCR-Bench.

<p align="center"><img src="https://raw.githubusercontent.com/OpenBMB/MiniCPM-OCR/main/assets/minicpm-ocr/efficiency-performance-en.png" alt="Throughput versus parsing quality for open-source OCR models. Horizontal axis: pages per second (log scale). Vertical axis: equal-weight average score across four document parsing benchmarks." width="90%"></p>

<sub>Average score is the equal-weight mean of the four benchmarks. All models use
accelerated configurations. Settings and reproduction: [reproduction guide](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/benchmark_reproduction_en.md).
Per-model throughput: [model guide](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/minicpm_ocr_1dot0_en.md#throughput).</sub>

## Benchmark comparisons

<p align="center"><img src="https://raw.githubusercontent.com/OpenBMB/MiniCPM-OCR/main/assets/minicpm-ocr/benchmark-radar.png" alt="Radar chart comparing MiniCPM-OCR 1.0 with other OCR models across six benchmarks." width="80%"></p>

### Full MiniCPM-OCR 1.0 evaluation results

<p align="center"><img src="https://raw.githubusercontent.com/OpenBMB/MiniCPM-OCR/main/assets/minicpm-ocr/ocr-benchmarks.png" alt="Detailed OCR model results on OmniDocBench v1.6, Real5-OmniDocBench, Wild-OmniDocBench, olmOCR-Bench, CHAOS-Bench, and OCRBench v2." width="100%"></p>

<p align="center"><img src="https://raw.githubusercontent.com/OpenBMB/MiniCPM-OCR/main/assets/minicpm-ocr/benchmark-comparison.png" alt="Per-benchmark bar charts for Real5-OmniDocBench, Wild-OmniDocBench, OmniDocBench v1.6, olmOCR-Bench, OCRBench v2, and CHAOS-Bench." width="100%"></p>

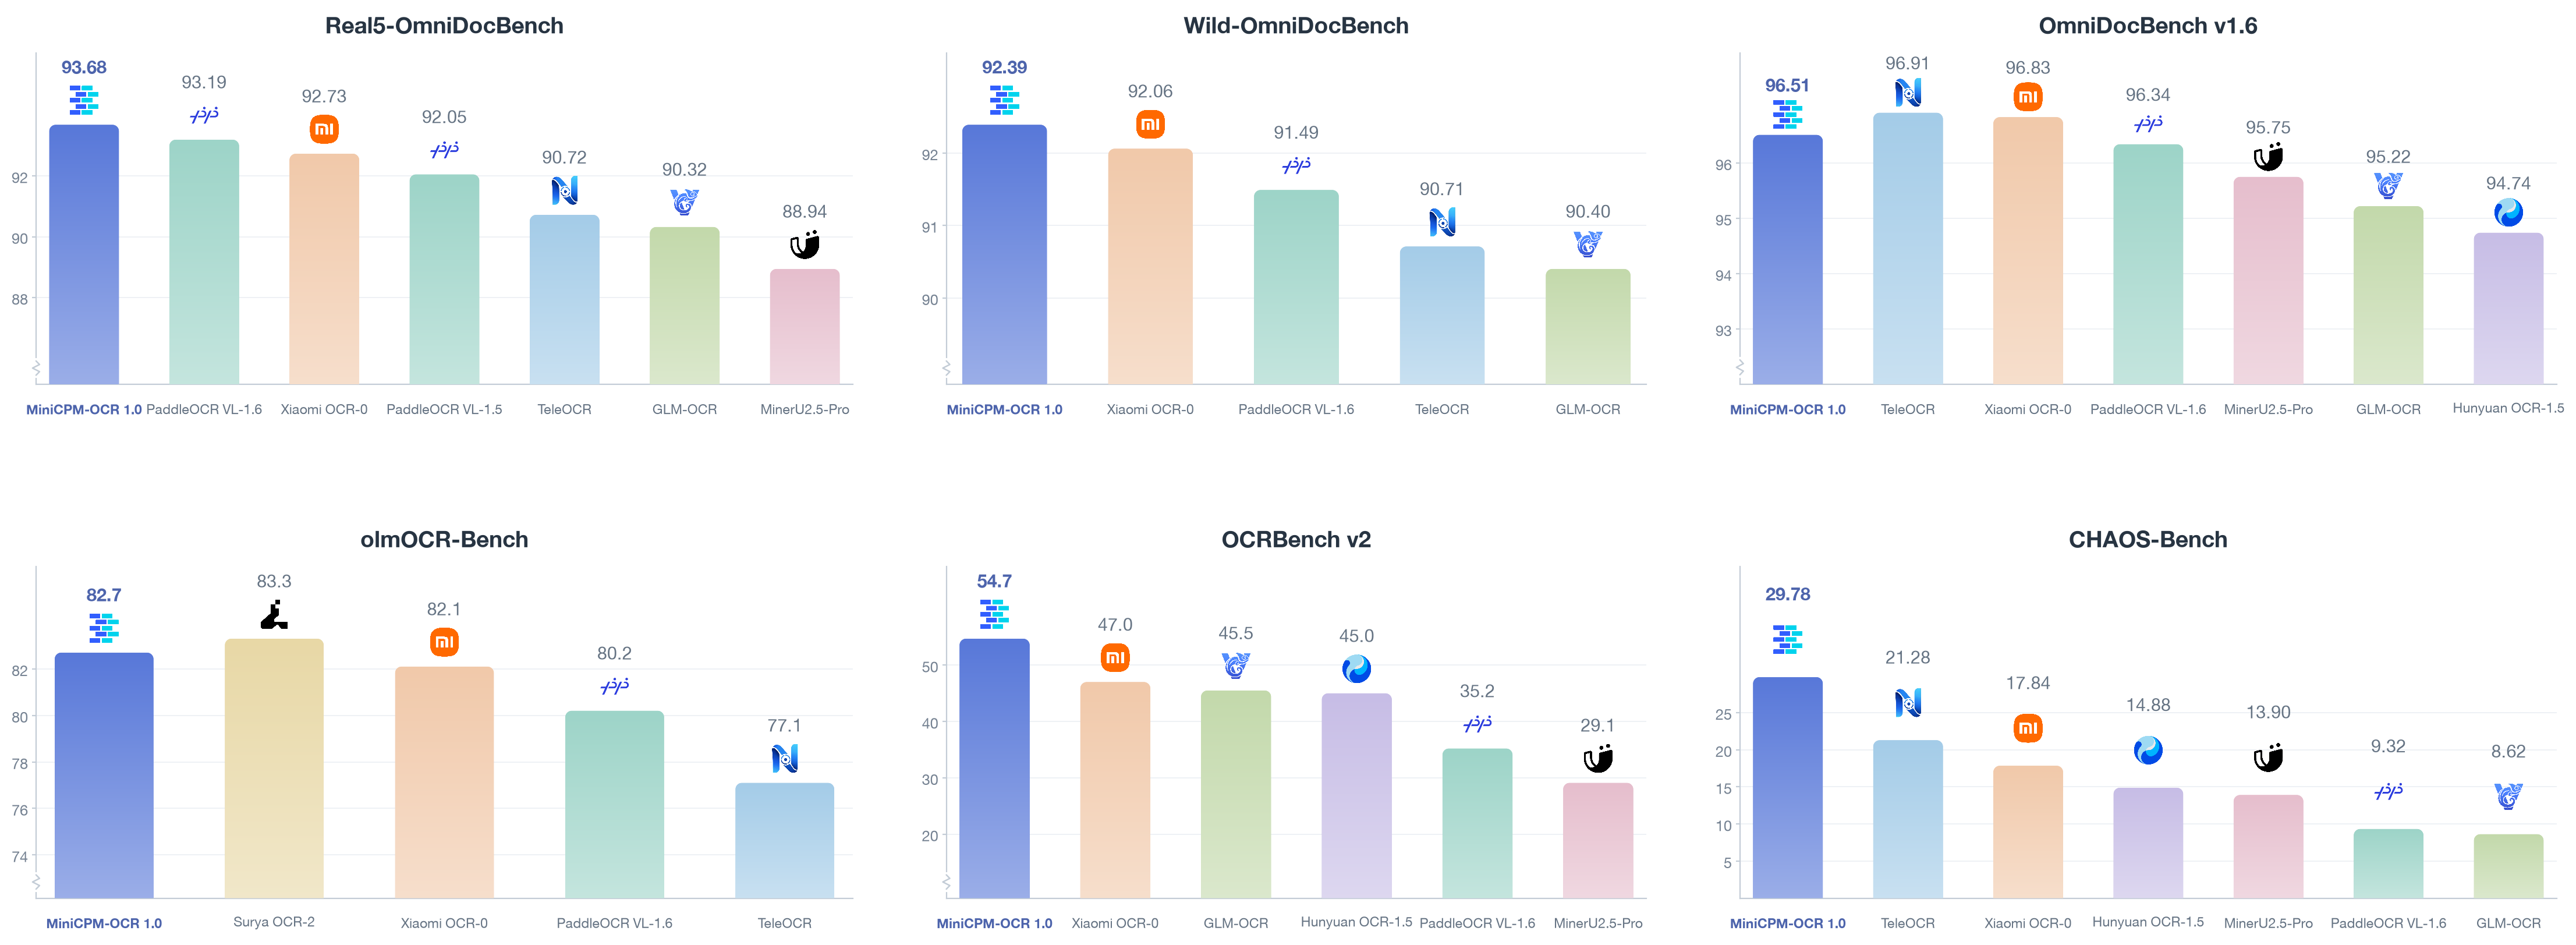
Each panel keeps its own benchmark's scores; higher is better. Scores from different
benchmarks are not directly comparable. Test settings and reproduction steps are in the
[reproduction guide](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/benchmark_reproduction_en.md); per-benchmark discussion is in the
[model guide](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/minicpm_ocr_1dot0_en.md#evaluation).

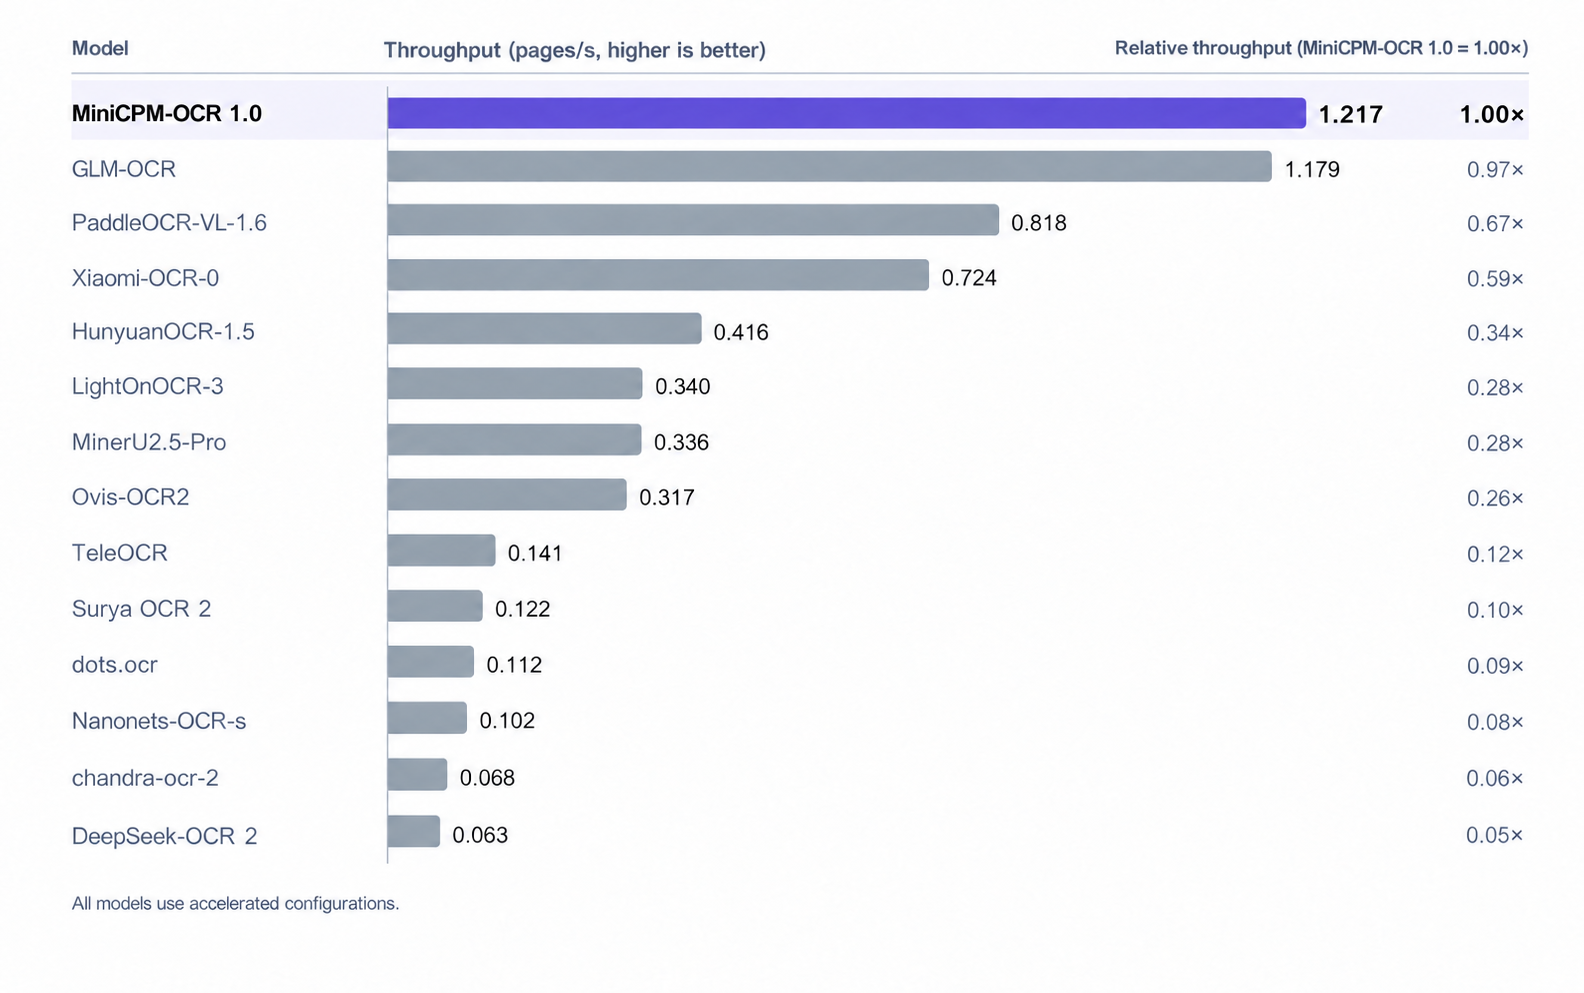
### Throughput

On an NVIDIA GeForce RTX 5090 with all 1651 OmniDocBench v1.6 images, image-level concurrency 1,
and each system's accelerated configuration, MiniCPM-OCR 1.0 reaches **1.2 pages/s**
(relative throughput **1.00×**; higher is faster).

<p align="center"><img src="https://raw.githubusercontent.com/OpenBMB/MiniCPM-OCR/main/assets/minicpm-ocr/throughput-comparison.png" alt="OCR system throughput with accelerated configurations; MiniCPM-OCR 1.0 achieves 1.2 pages/s." width="100%"></p>

Concurrency 1 is image-level: regions inside a page are still recognised in parallel.
Real throughput also depends on page content, backend, concurrency, and hardware.

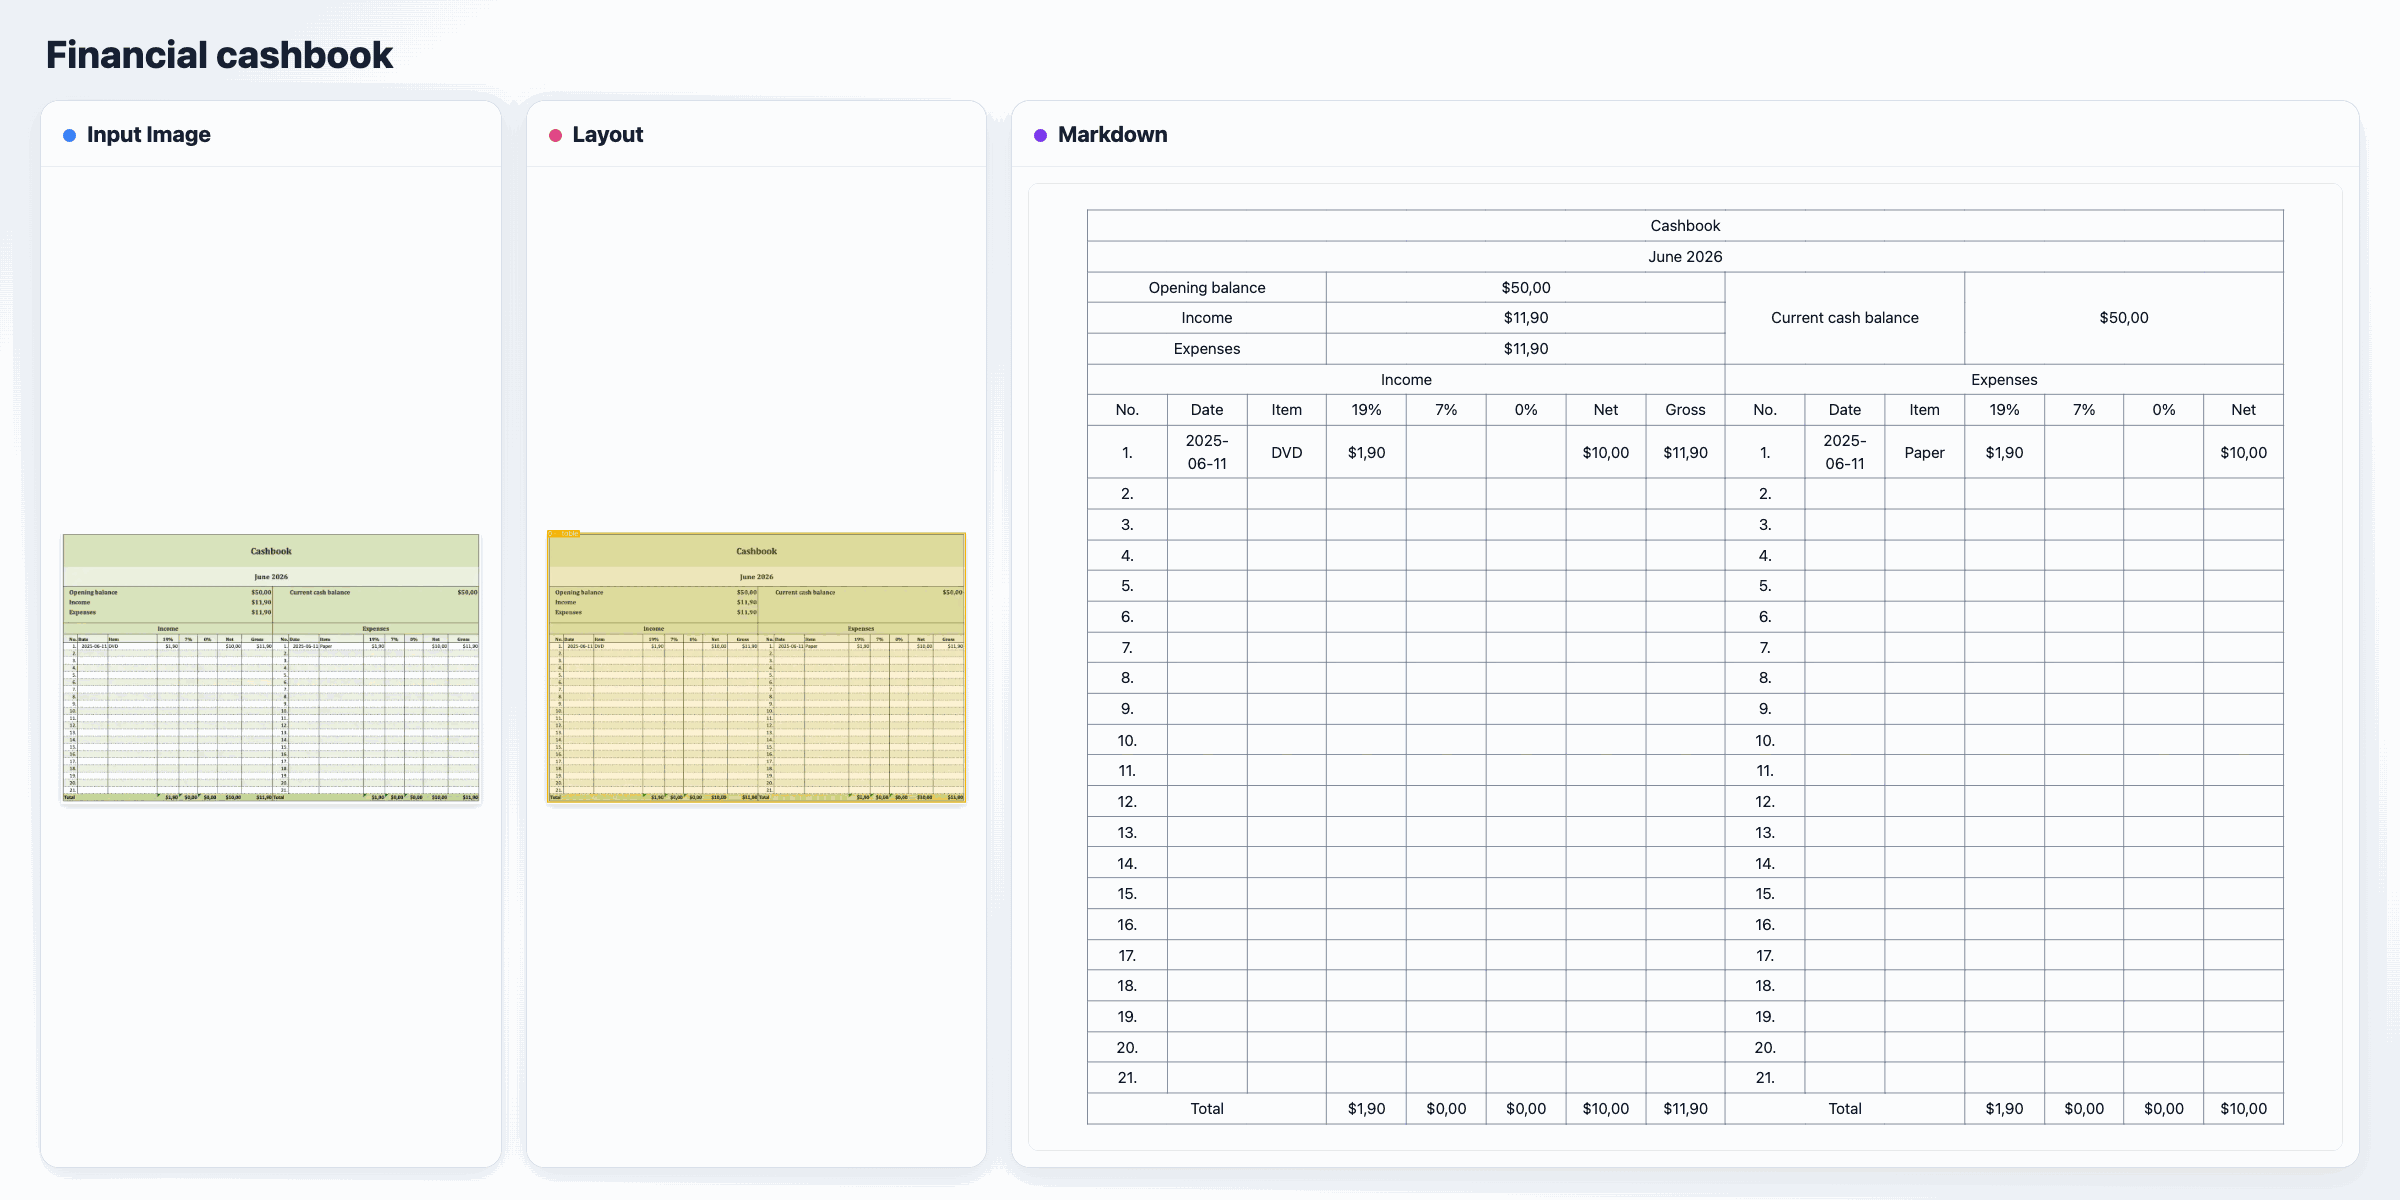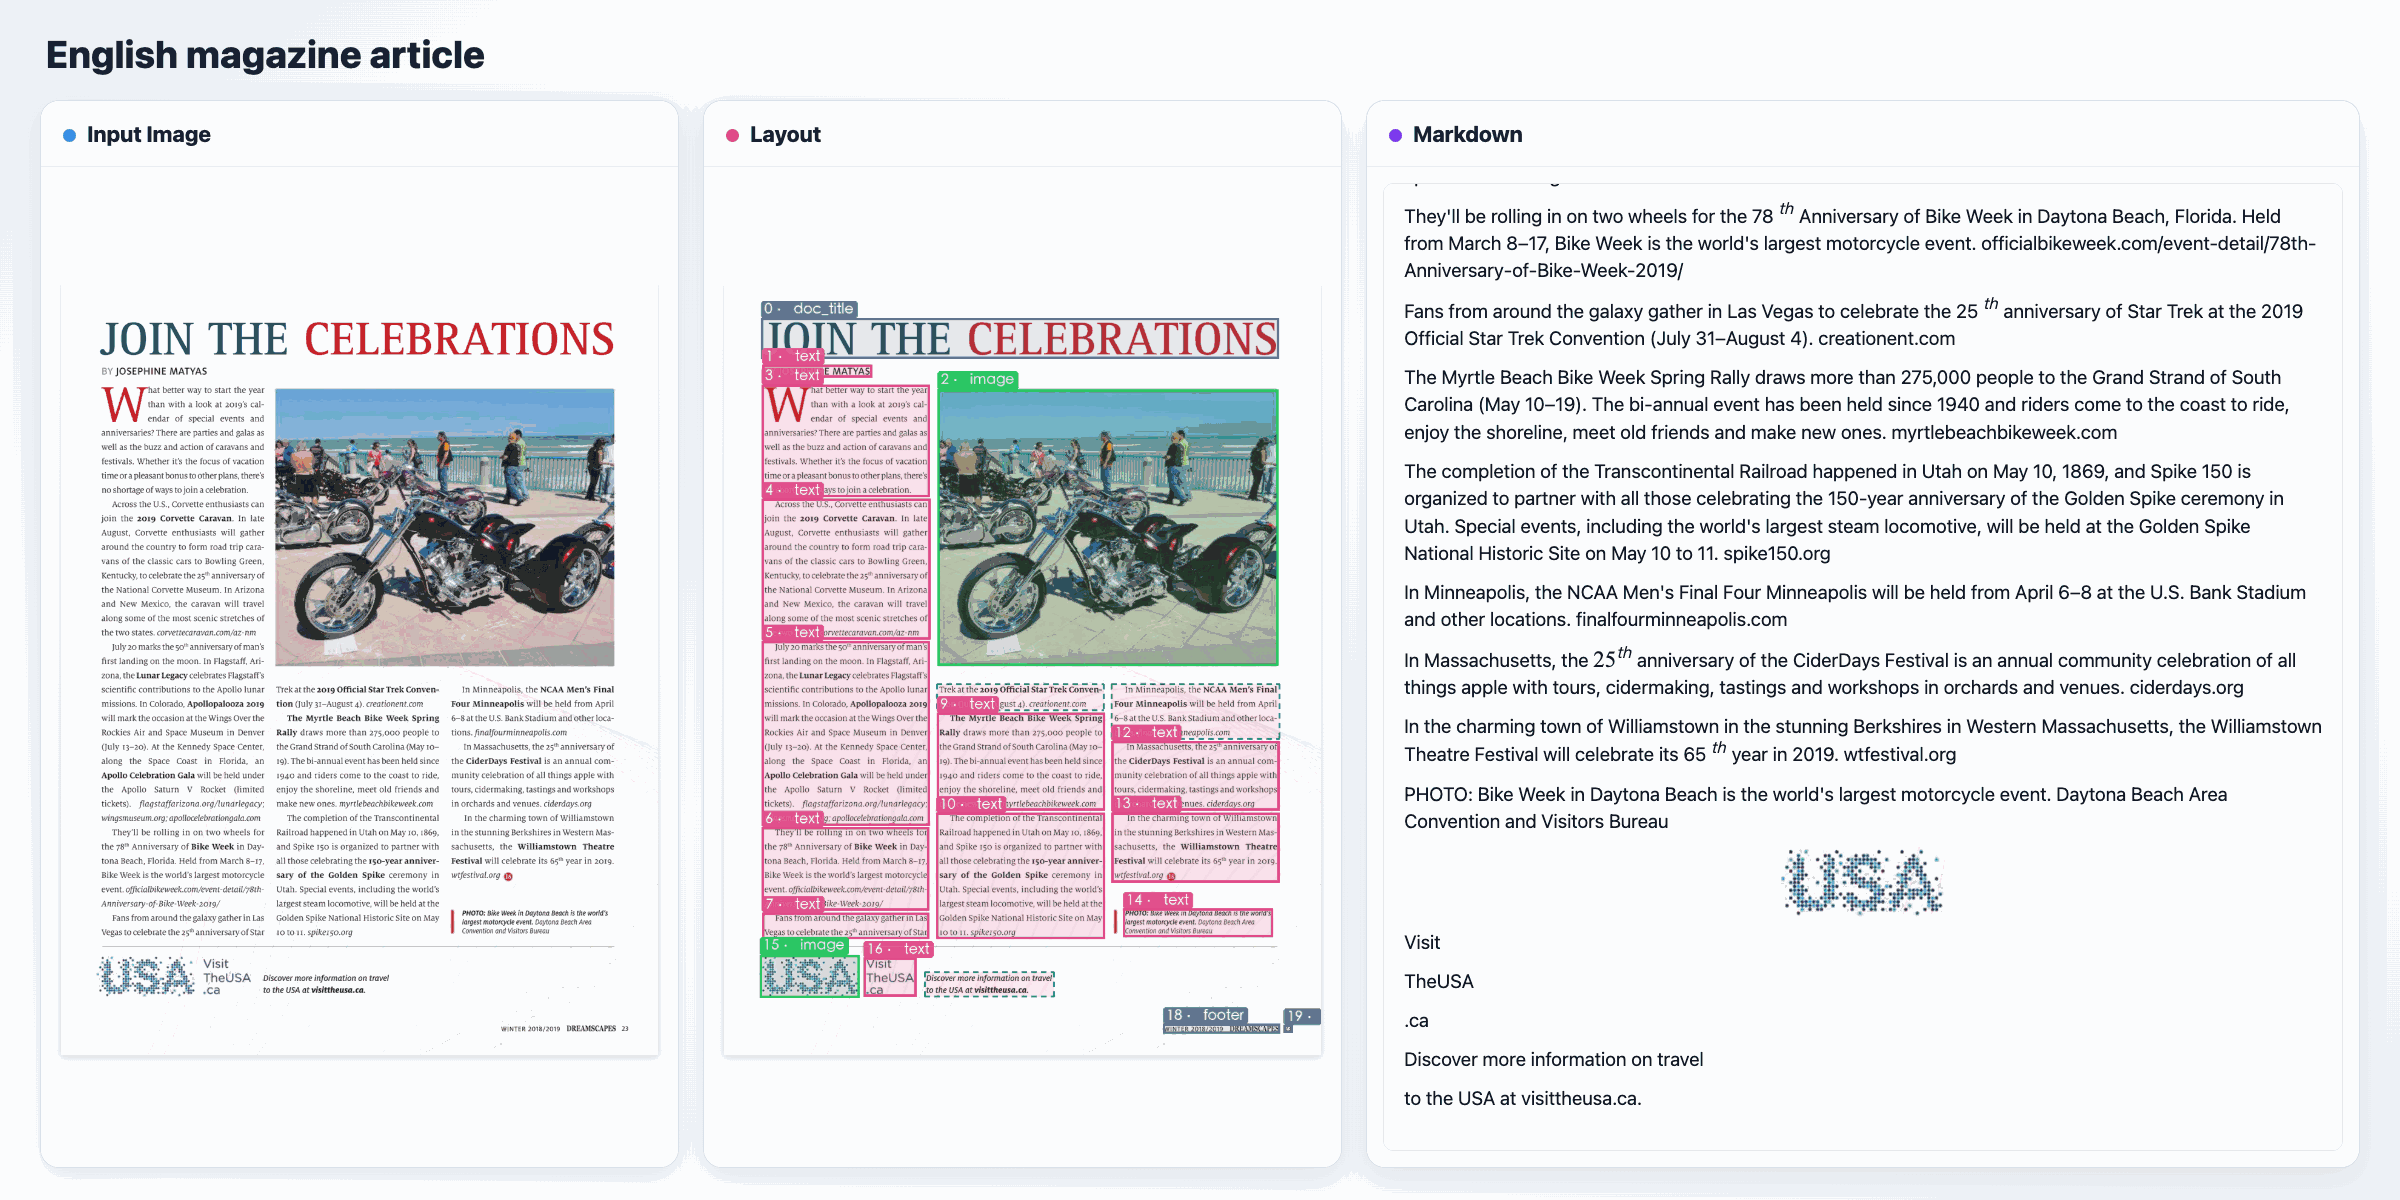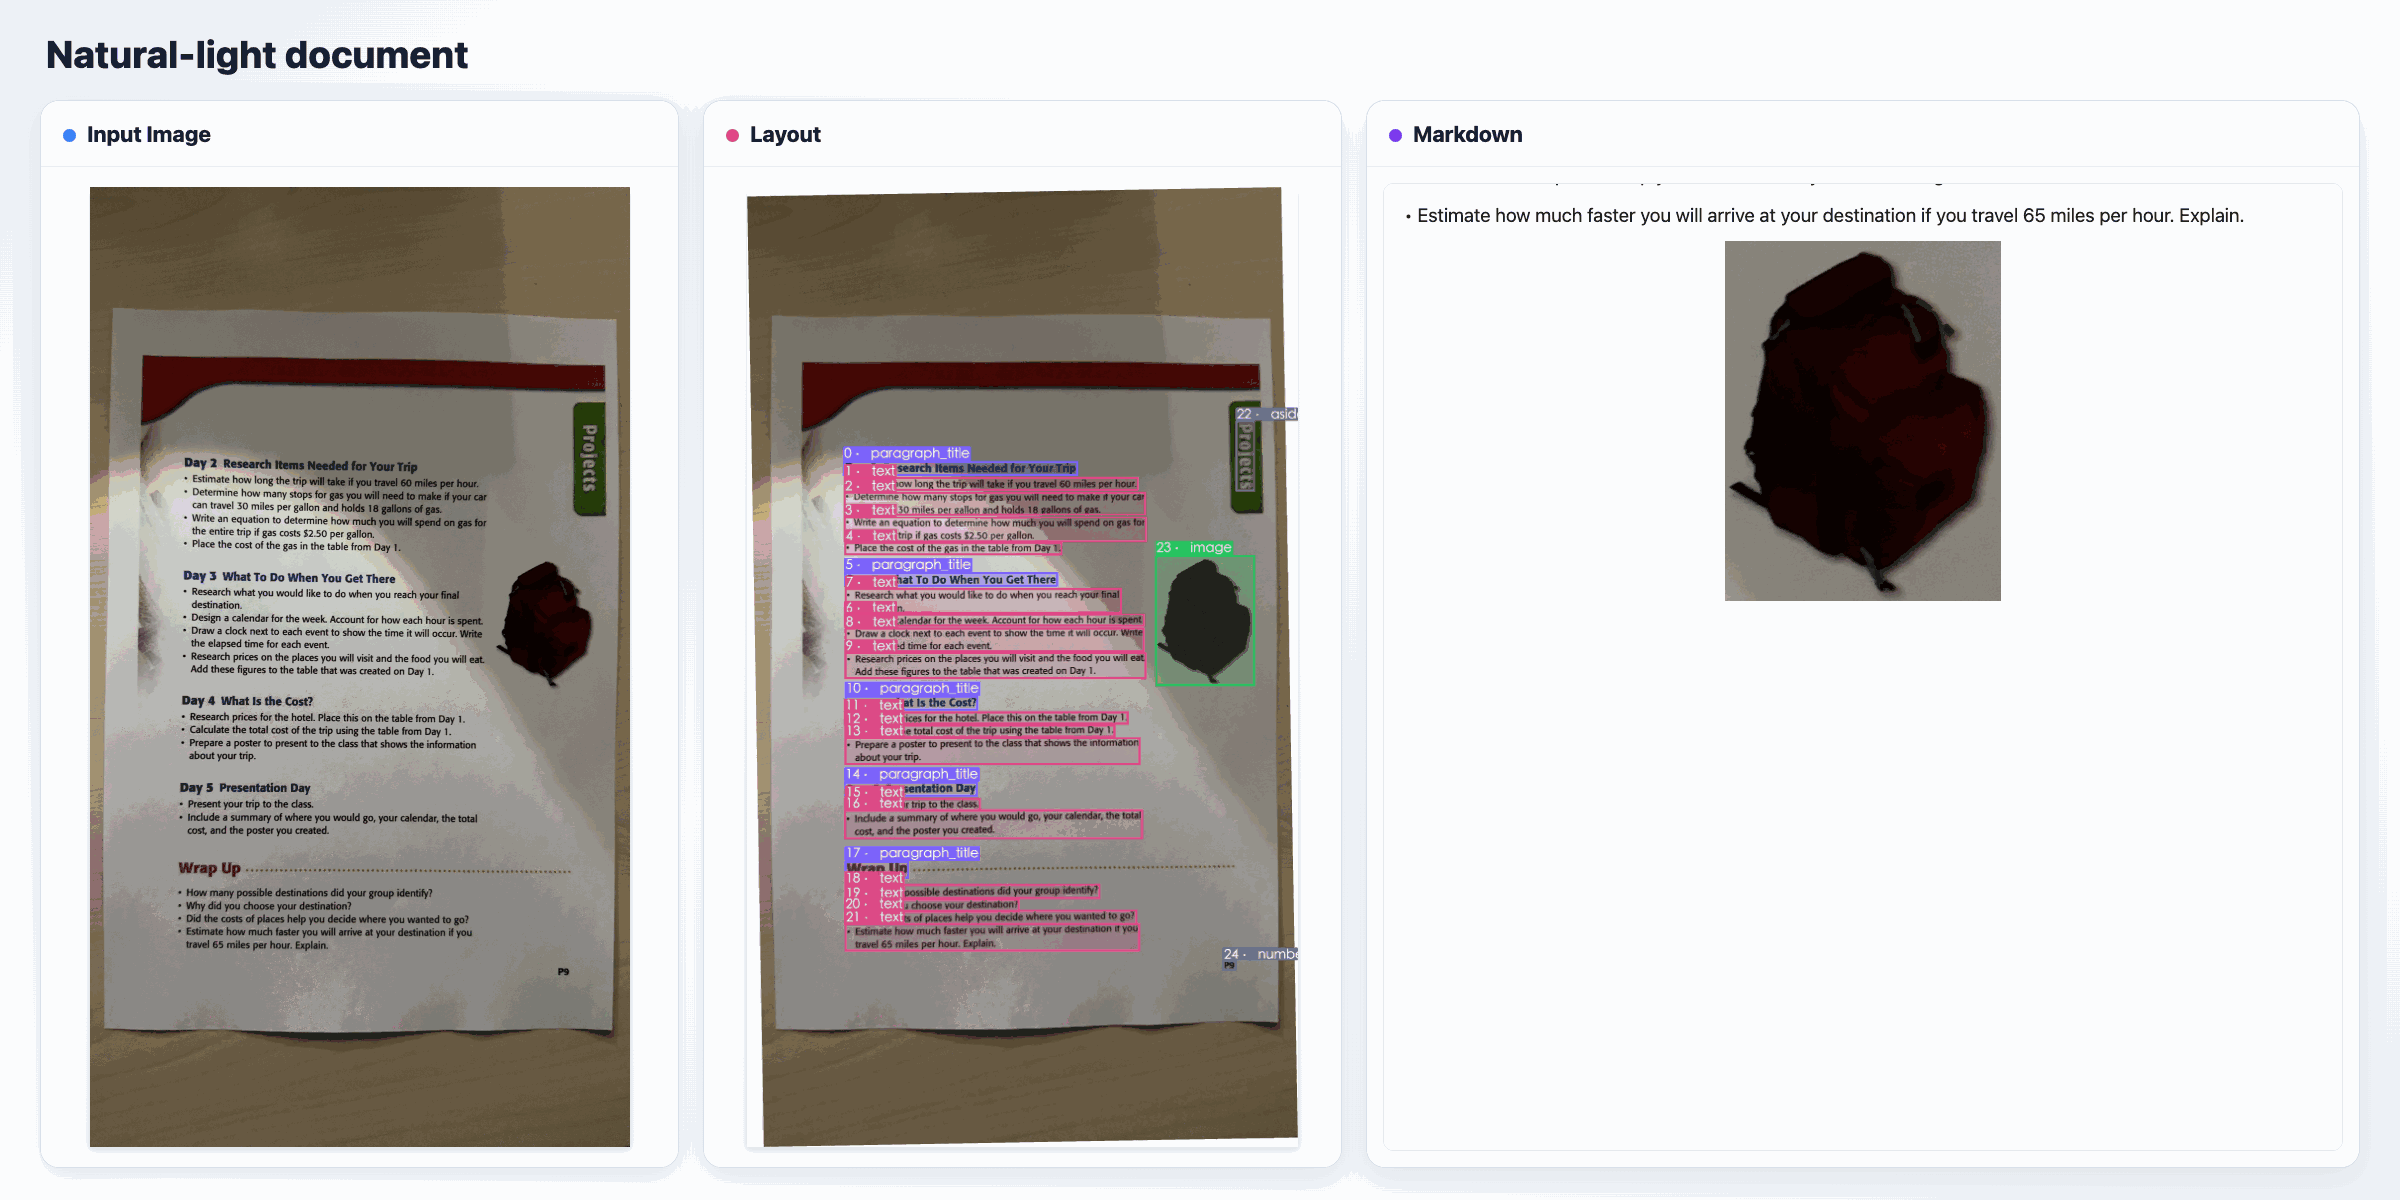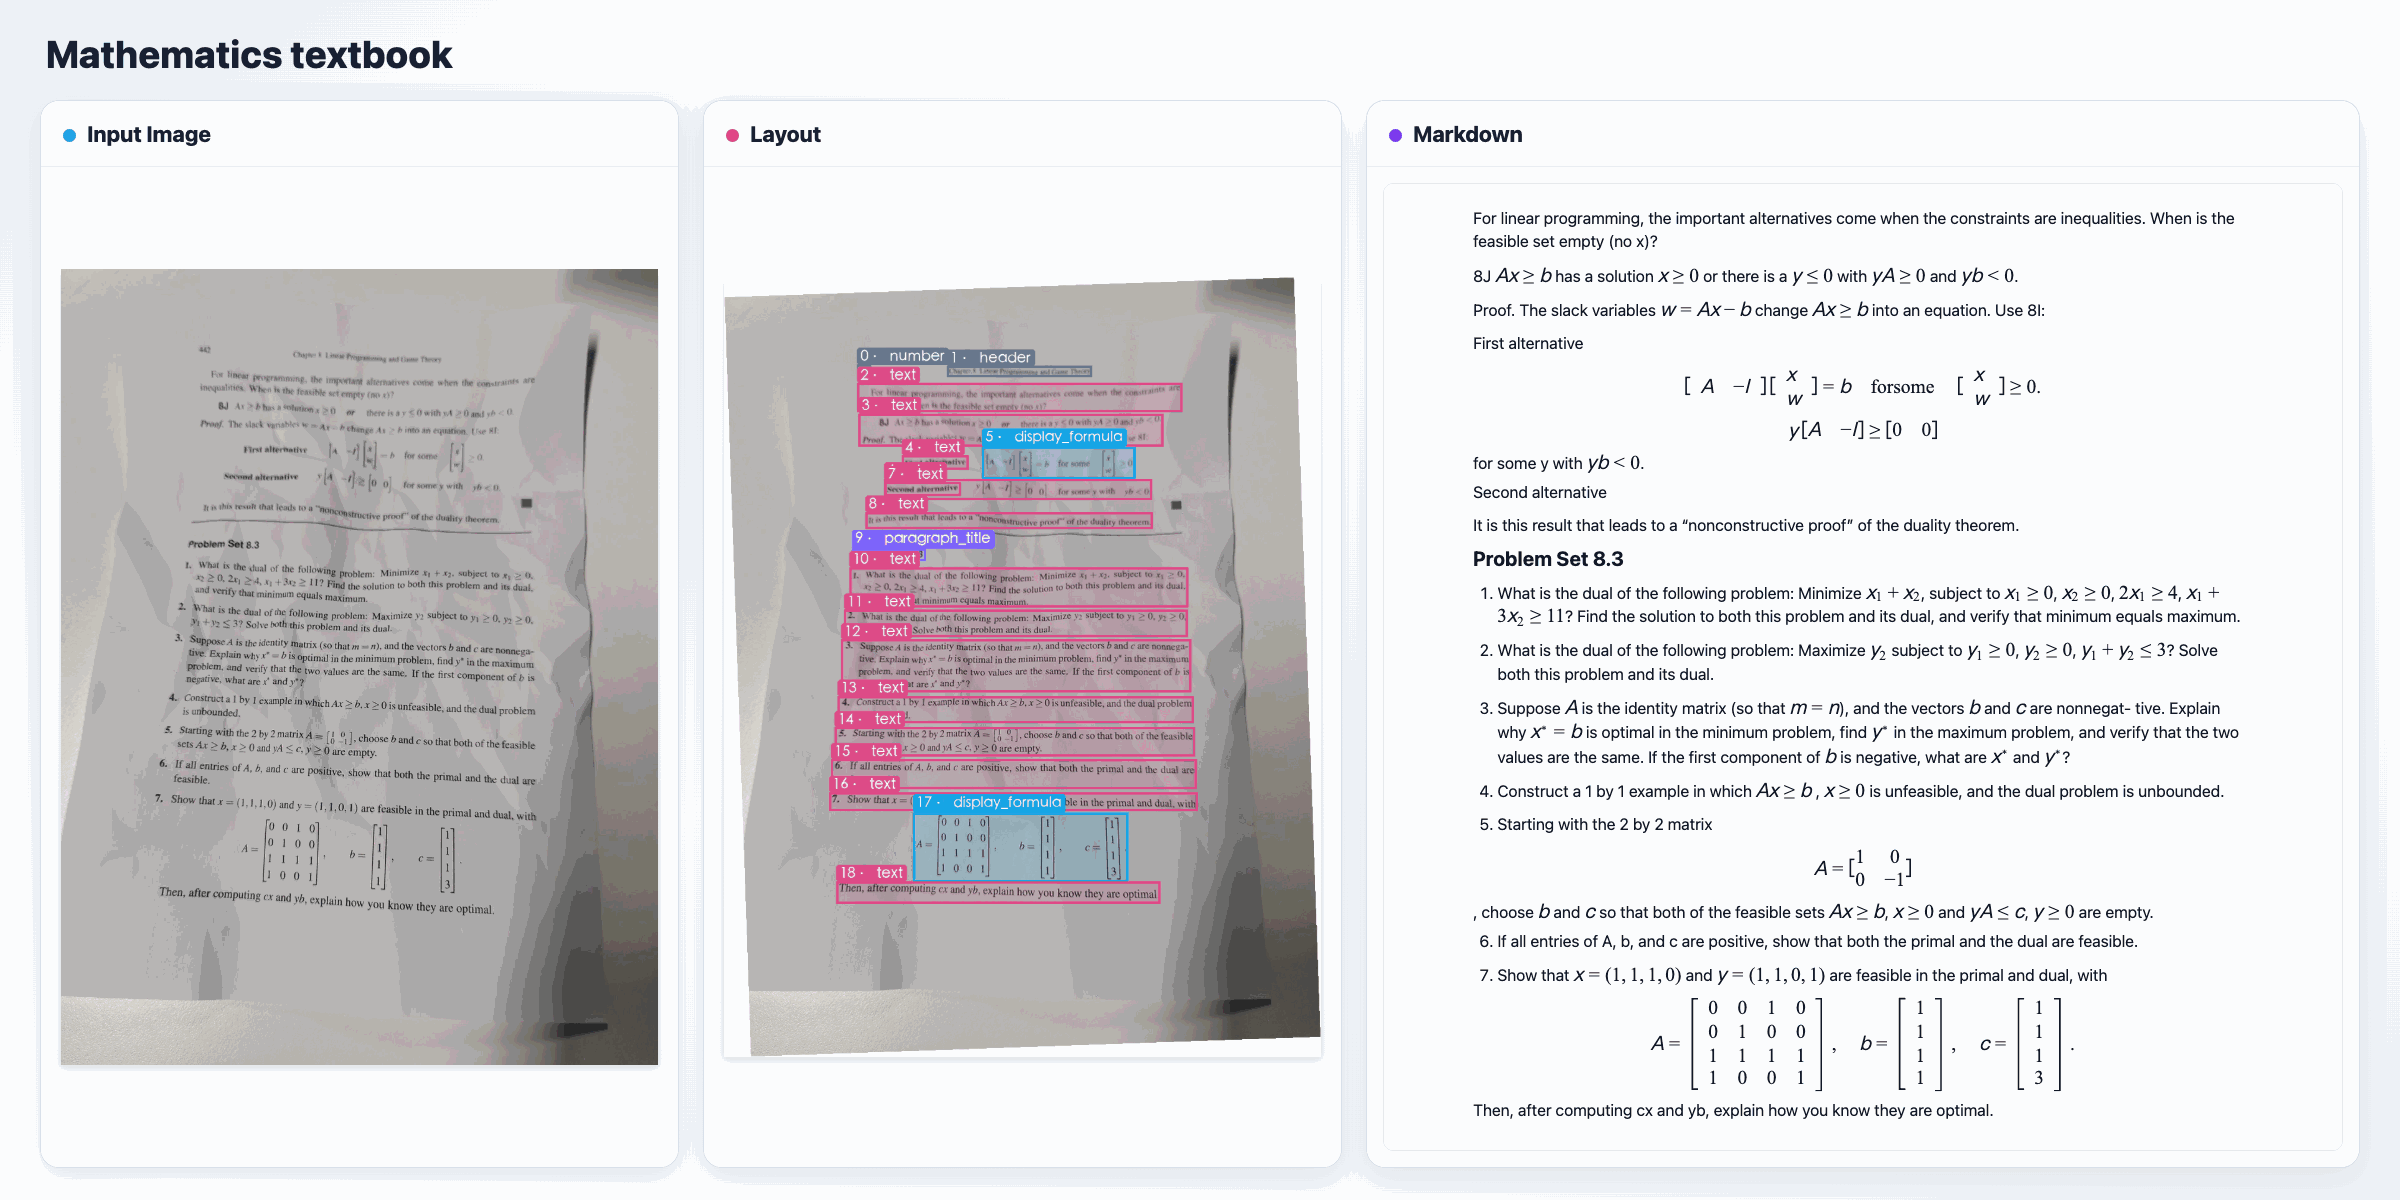
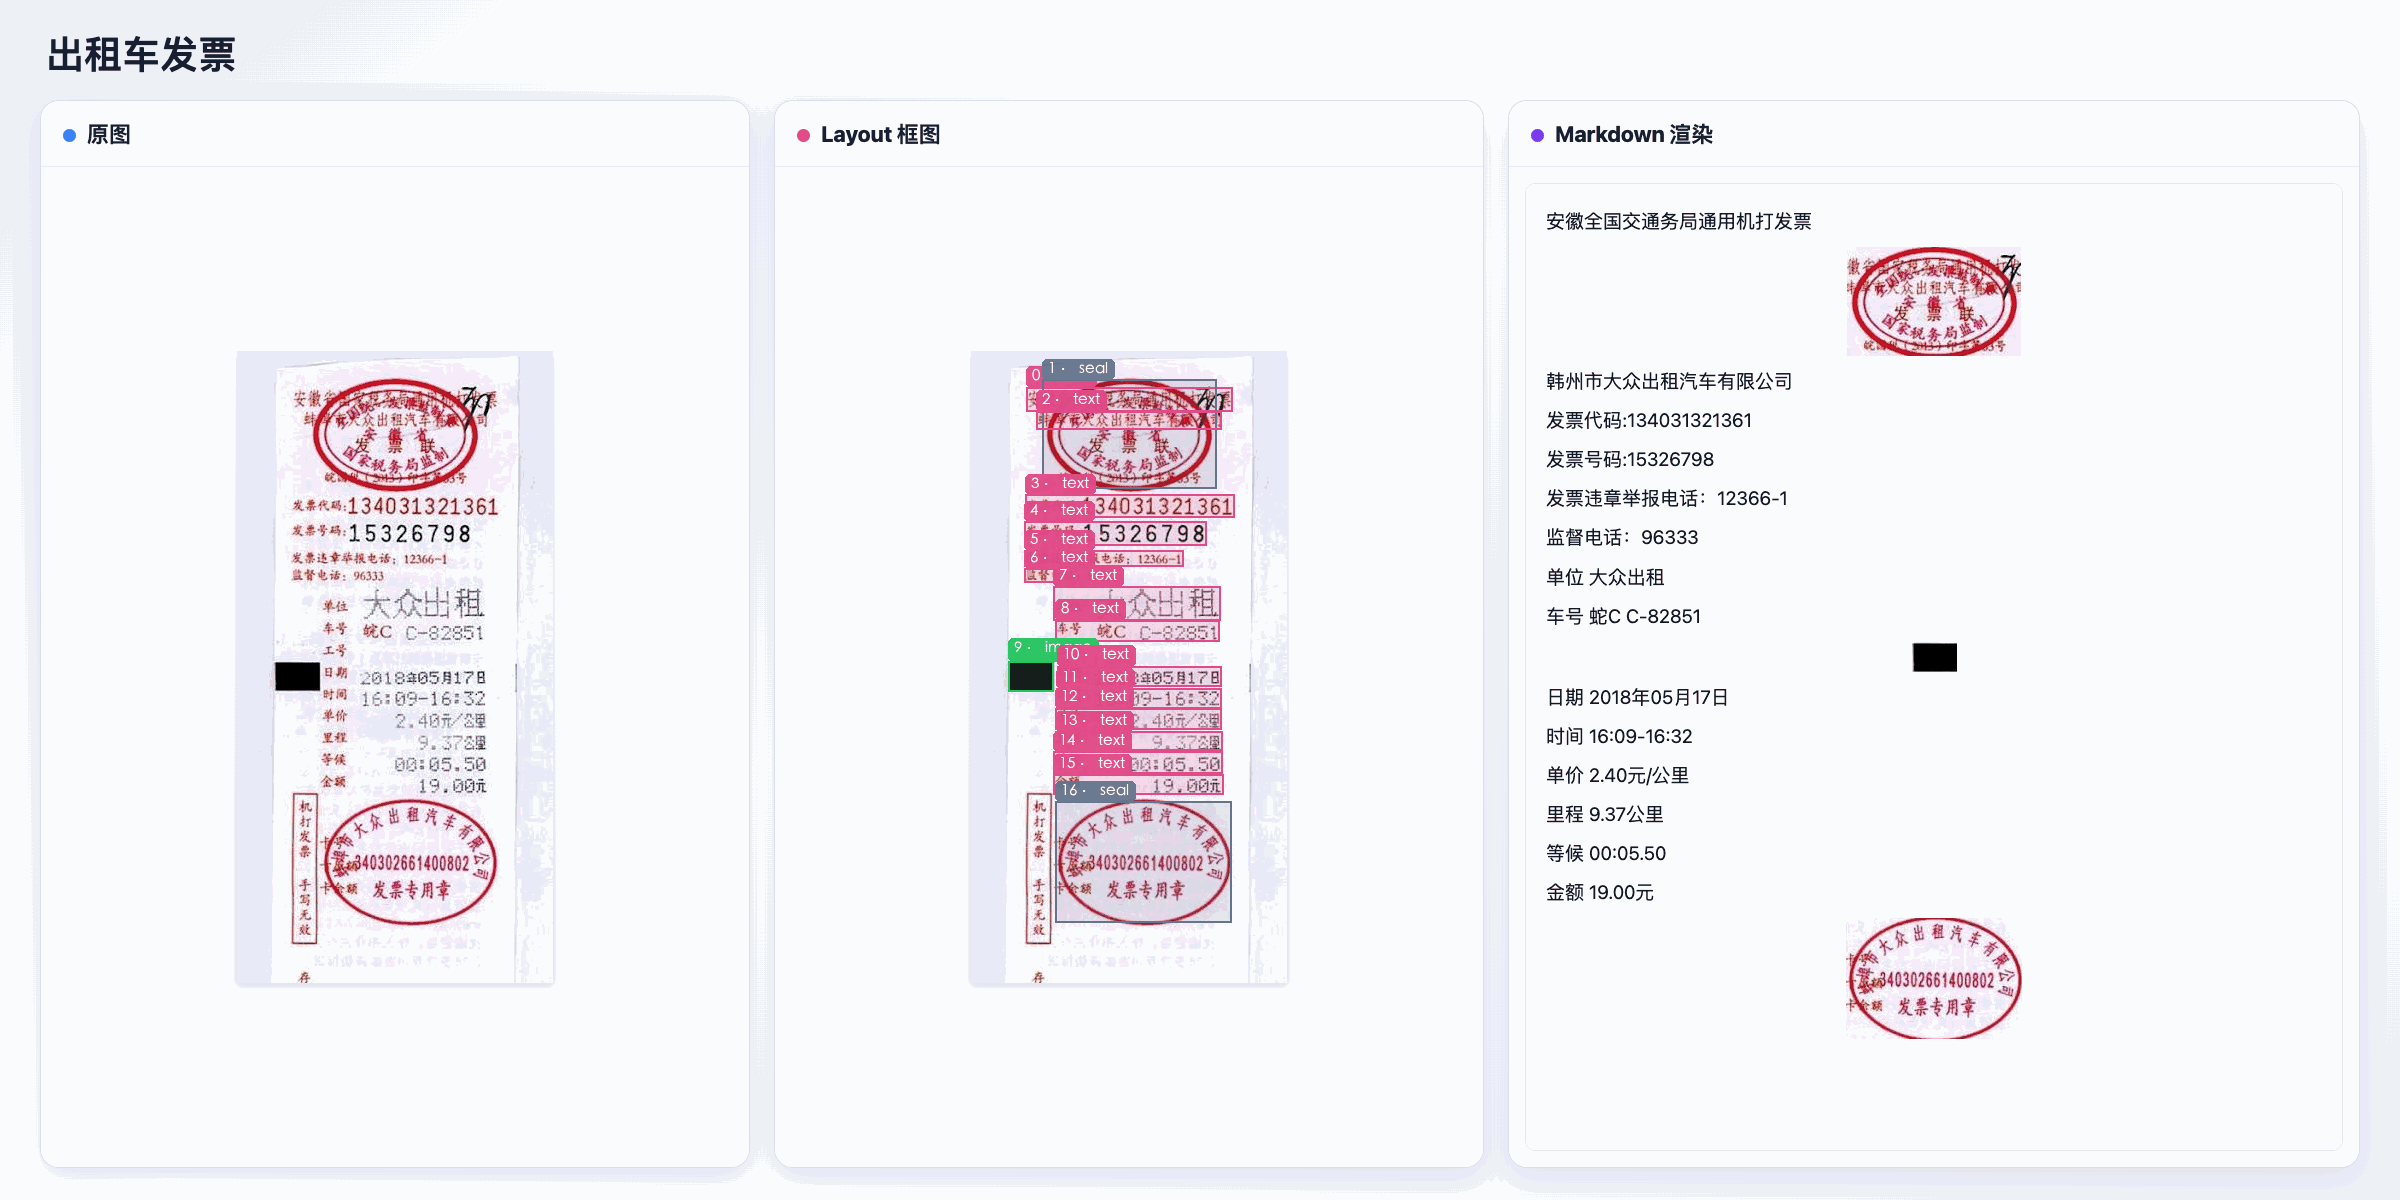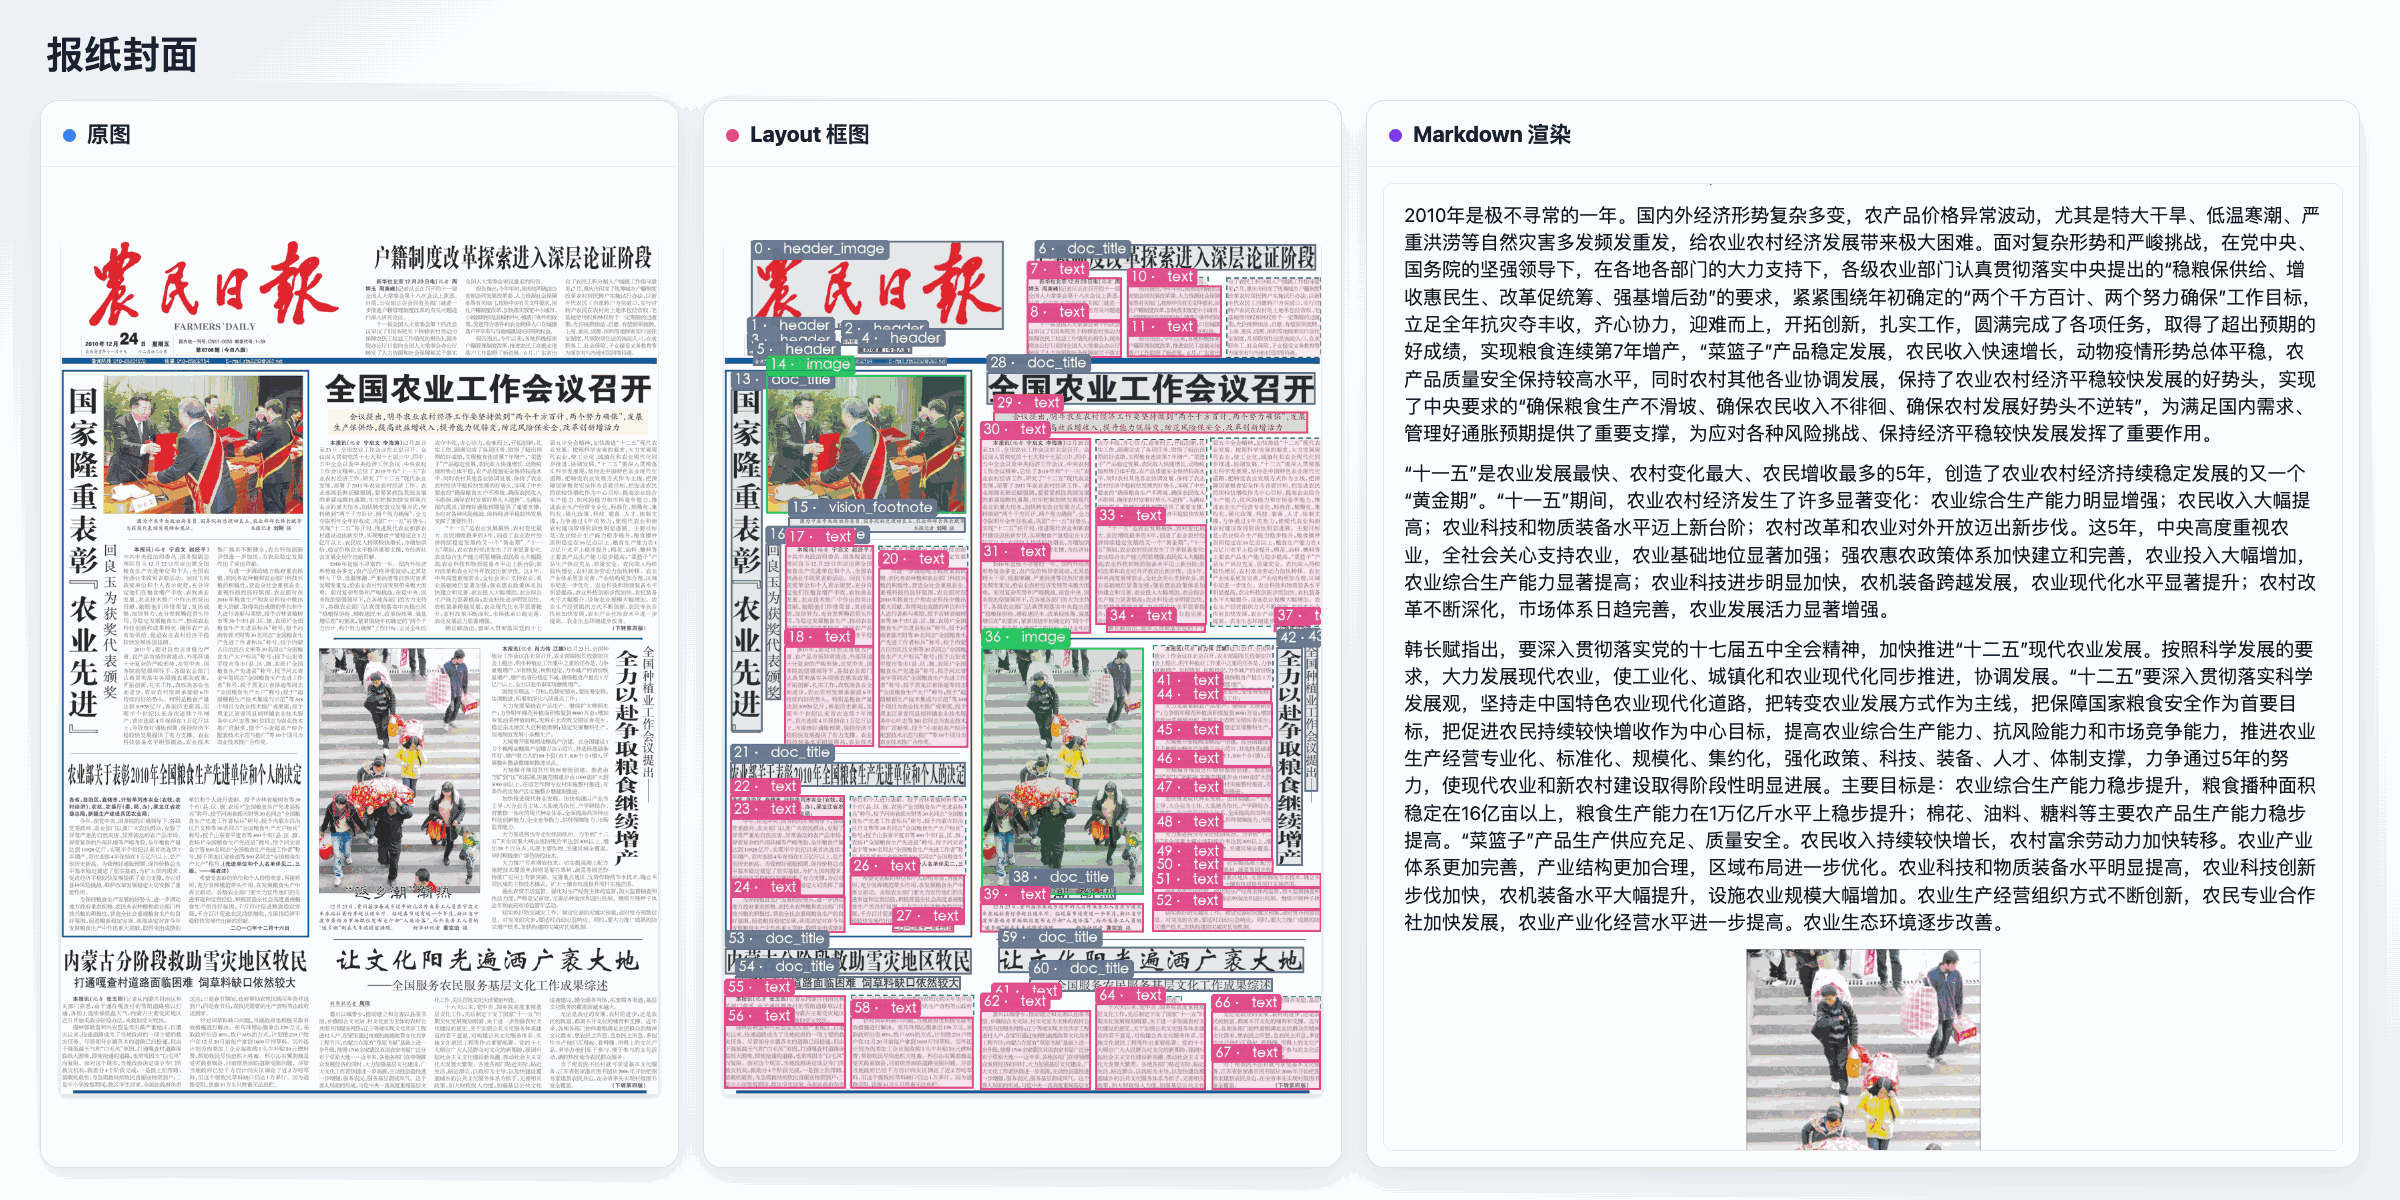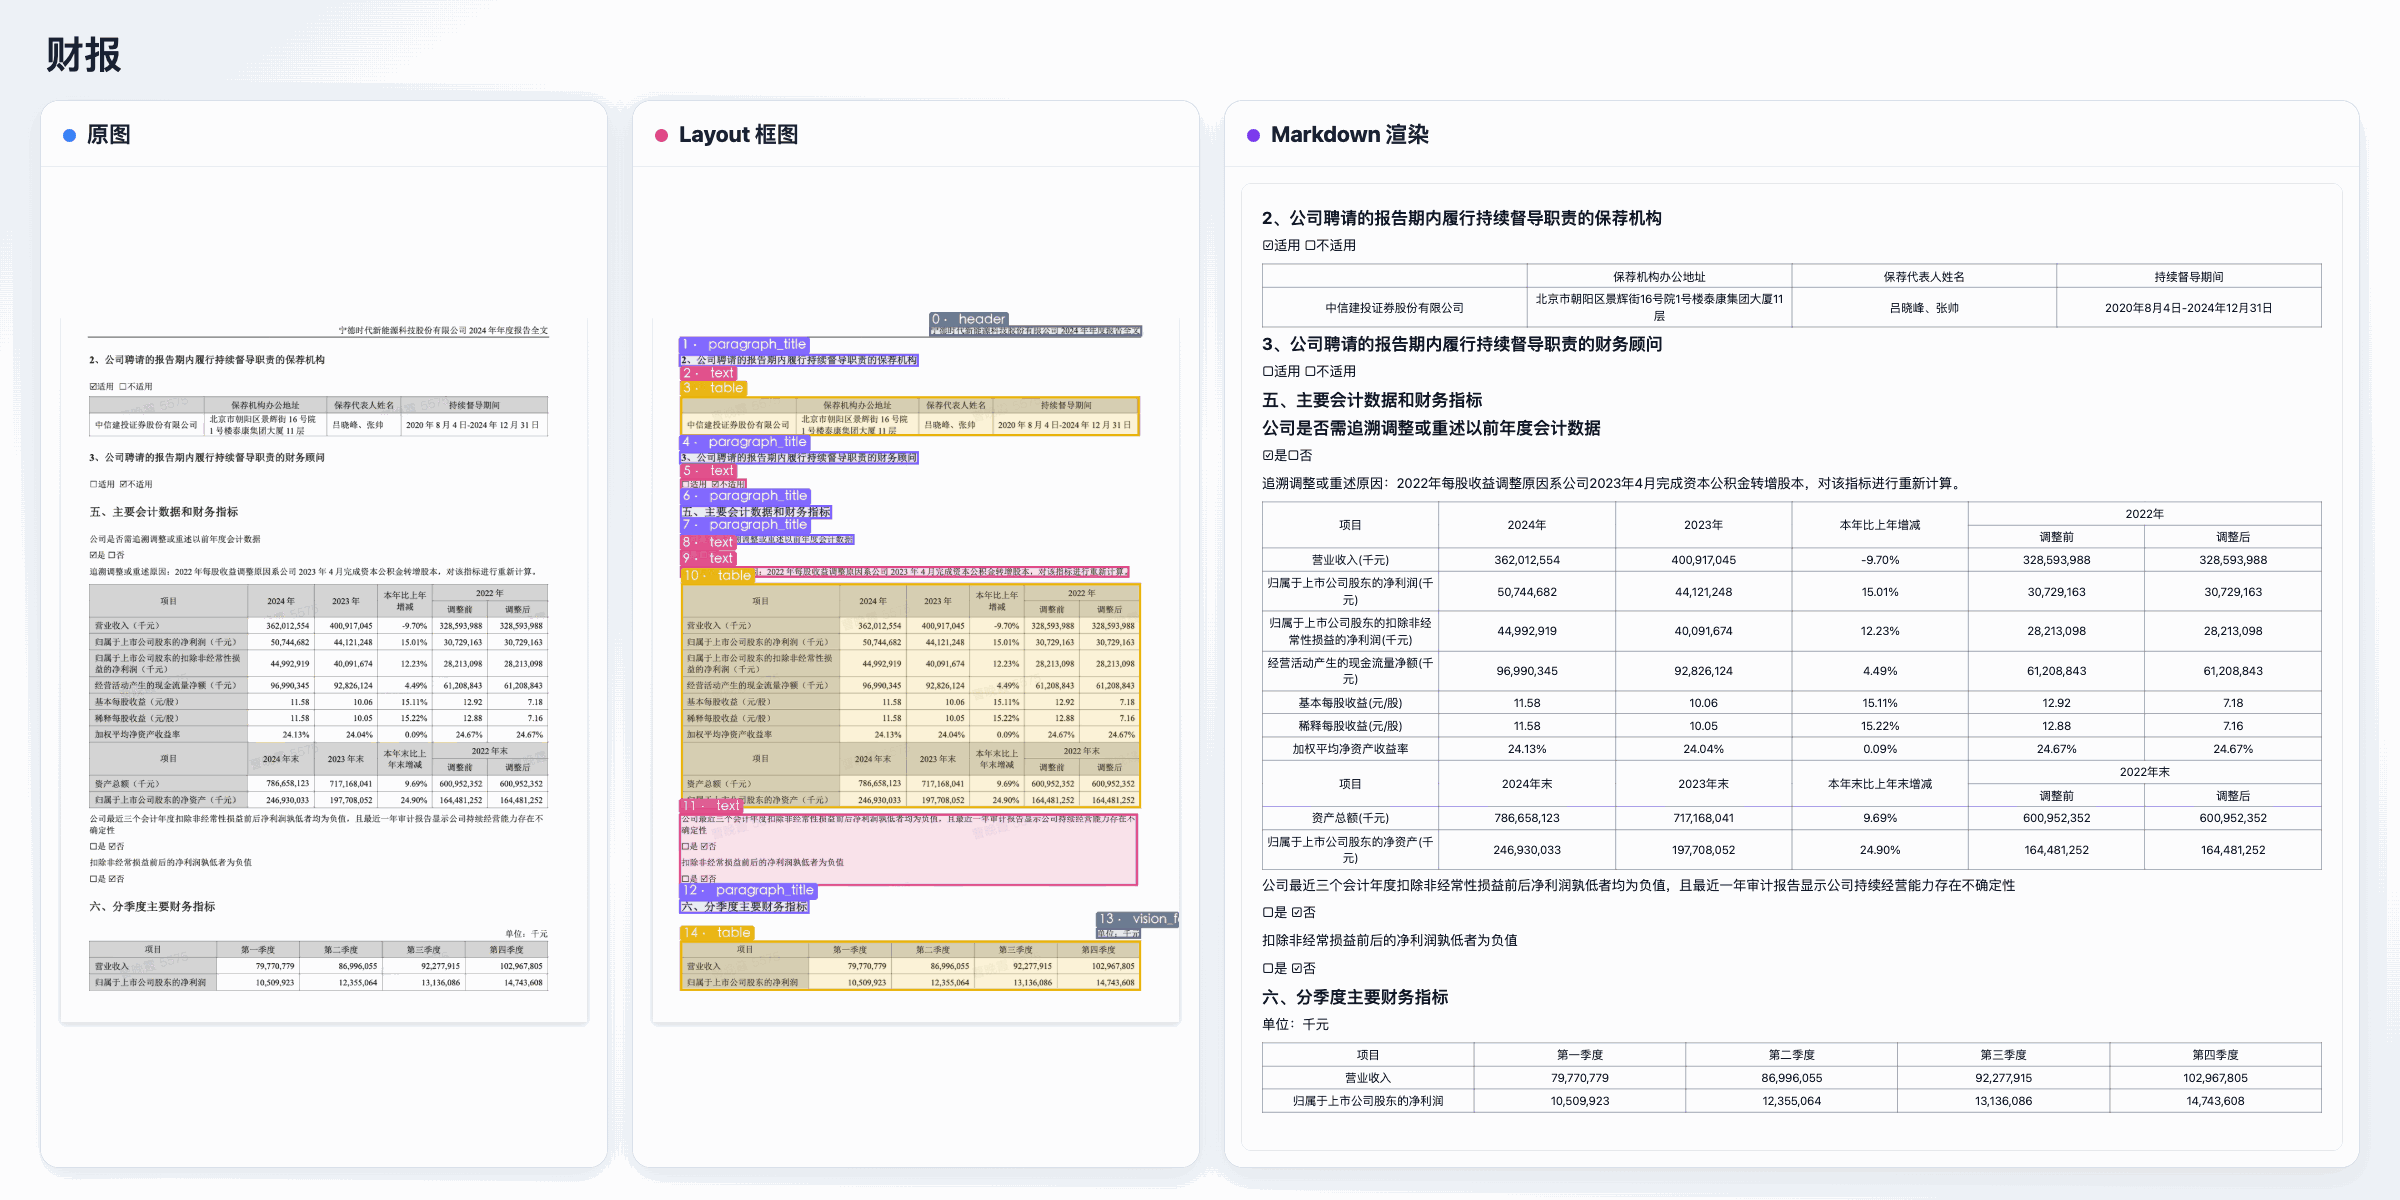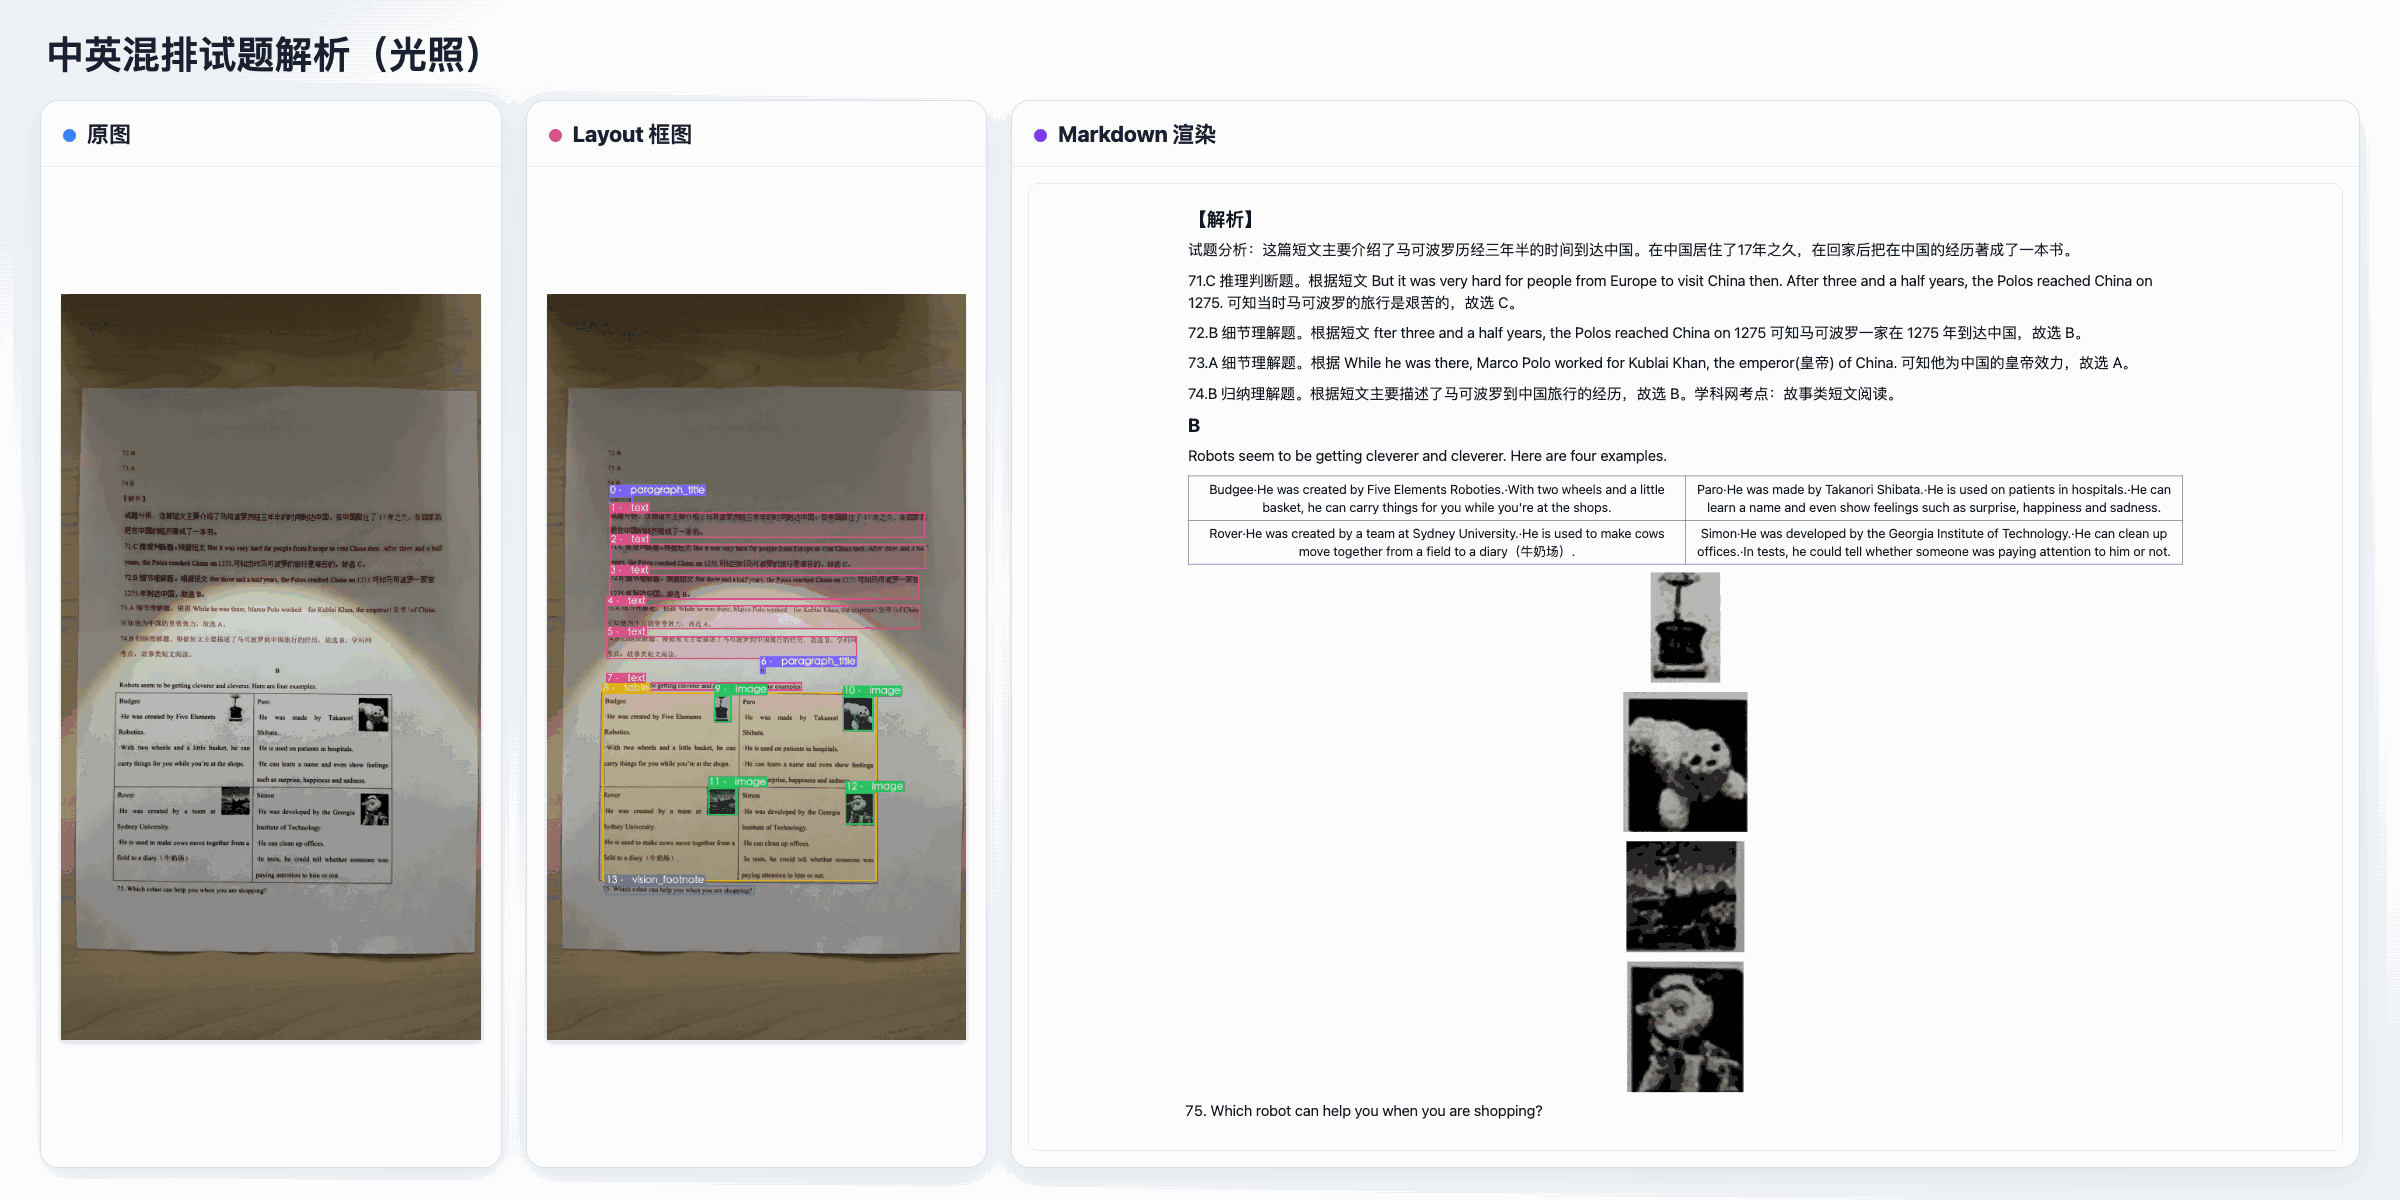
## Examples

Left to right: original document, detected layout, and rendered Markdown.

**English documents**

<p align="center"><img src="https://raw.githubusercontent.com/OpenBMB/MiniCPM-OCR/main/assets/minicpm-ocr/minicpm-english-examples-3-column.gif" alt="English document animation: original, detected layout, and rendered Markdown." width="100%"></p>

**Chinese documents**

<p align="center"><img src="https://raw.githubusercontent.com/OpenBMB/MiniCPM-OCR/main/assets/minicpm-ocr/minicpm-chinese-examples-3-column.gif" alt="Chinese document animation: original, detected layout, and rendered Markdown." width="100%"></p>

### More examples

Original documents and parsed results, side by side.

**English documents**

<p align="center"><img src="https://raw.githubusercontent.com/OpenBMB/MiniCPM-OCR/main/assets/minicpm-ocr/minicpm-ocr-english-cases.png" alt="English examples comparing inputs and results: handwriting, historical and scanned documents, newspapers, financial statements, and key information extraction." width="100%"></p>

**Chinese documents**

<p align="center"><img src="https://raw.githubusercontent.com/OpenBMB/MiniCPM-OCR/main/assets/minicpm-ocr/minicpm-ocr-chinese-cases.png" alt="Chinese examples comparing inputs and results: handwritten notes, complex formulas, newspapers, financial statements, stamped documents, illustrations, and key information extraction." width="100%"></p>

## Model architecture

| Item | Description |
| :--- | :--- |
| Parameters | 1.3B |
| Base | Trained for OCR on top of MiniCPM-V 4.6 |
| Components | SigLIP vision encoder + Qwen3.5 language model |
| Primary languages | Chinese and English |
| Tasks | Text, tables, formulas, charts, seals, and key information extraction |
| Parsing pipeline | MiniCPM-OCR 1.0 + PP-DocLayoutV3 layout model + `minicpmvocr` SDK |
| Visual tokens | 4× compression, `scale_resolution` 448, up to 9 slices |

See the [model guide](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/minicpm_ocr_1dot0_en.md) for architecture, parsing workflow,
deployment options, and benchmark breakdowns.

## Quick start

### Use with the MiniCPM-OCR SDK

> **Required before using either the CLI or Python API:** deploy and start the OCR model service first, and wait until it is ready to accept requests. The SDK examples below are clients of that running service; they do not deploy or start the OCR model service automatically.

Use the official `minicpm-ocr` SDK to parse local images or PDFs with this
AWQ checkpoint. The SDK detects layout with PP-DocLayoutV3, recognises each
region, and saves structured JSON and Markdown in reading order.

Install Python 3.10+ and the SDK:

```bash
pip install "minicpm-ocr[all]"
```

Install minicpm-ocr for your platform using the
[installation guide](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/minicpm_ocr_tutorial_en.md#1-set-up-the-sdk-environment).

#### Prerequisite: deploy and start the model service

Before running the SDK, start a vLLM recognition service for the **AWQ checkpoint
in this repository**, `openbmb/MiniCPM-OCR-1.0-AWQ`, following the
[vLLM deployment guide](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/vllm_deploy_en.md).
Use this repository ID as the served model path, `--served-model-name minicpm-ocr`,
`--port 8080`, and `--max-model-len 40960`. The service reads the AWQ
quantization settings from this repository's `config.json`.

The SDK examples use `http://127.0.0.1:8080`, model alias `minicpm-ocr`, the
`vllm` backend, and an NVIDIA GPU for layout detection. Match the URL, alias,
and context length to your service. The SDK connects to the running service;
it does not load the quantized weights into the SDK process.

#### CLI

**Start the model service described above and wait until it is ready before running this command.**
Save a local image as `demo.png`, then run:

```bash
minicpmvocr parse demo.png \
  --backend vllm \
  --server-url http://127.0.0.1:8080 \
  --model minicpm-ocr \
  --device cuda:0 \
  --set engine.max_model_len=40960 \
  --set run.run_root=output \
  --output output/demo.md
```

The CLI automatically downloads PP-DocLayoutV3 to `models/PP-DocLayoutV3_infer/`
when needed. The final Markdown is saved to `output/demo.md`; structured JSON
and per-page Markdown are kept in `output/<run_tag>/results_json/` and
`output/<run_tag>/output/`.

#### Python API

**The model service described above must already be running before you execute this Python example.**
Set `engine.server_url` and `engine.model_name` to match that service.

The same pipeline is available from Python:

```python
from importlib.resources import files
from pathlib import Path

from minicpmvocr import load_config, pipelined_run
from minicpmvocr.layouts.download import ensure_layout_model


def main():
    layout_model = ensure_layout_model(Path("models/PP-DocLayoutV3_infer"))

    cfg = load_config(
        str(files("minicpmvocr").joinpath("configs/minicpmvocr.yaml")),
        overrides={
            "input": {"file_path": str(Path("demo.png").resolve())},
            "engine": {
                "type": "vllm",
                "server_url": "http://127.0.0.1:8080",
                "model_name": "minicpm-ocr",
                "max_model_len": 40960,
            },
            "layout": {
                "model_dir": str(layout_model),
                "device": "cuda:0",
            },
            "pipeline": {"overlap_layout": True},
            "run": {"run_root": str(Path("output").resolve())},
        },
    )

    pipelined_run(cfg)

    print("JSON directory:", cfg["_meta"]["result_json_dir"])
    print("Markdown directory:", cfg["_meta"]["output_dir"])


if __name__ == "__main__":
    main()
```

`ensure_layout_model()` reuses or downloads the official layout model.
Results are written to `output/<run_tag>/results_json/` and
`output/<run_tag>/output/`. To parse a PDF, replace `demo.png` with its local path.

For CPU layout detection, use `--device cpu` in the CLI or set `layout.device`
to `cpu` in Python. This changes only the layout detector; the recognition
service still uses the deployed quantized model.

Run `minicpmvocr parse --help` for CLI options, or see the
[SDK API reference](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/minicpm_ocr_sdk_api_en.md)
for configuration and document-level Markdown export.

### Prompts

The prompt selects the task and must match the region you cropped:

| Region | Prompt | Output |
| :--- | :--- | :--- |
| Text block / paragraph / title / page | `Text Recognition:` | plain text |
| Table | `Table Recognition:` | HTML (via SDK post-processing) |
| Formula | `Formula Recognition:` | LaTeX |
| Inline formula | `Text Recognition:` | LaTeX |
| Seal | `Seal Recognition:` | seal text |
| Chart | `Chart to Table:` | table |

If `finish_reason` is `length`, the output was truncated — raise the token budget.

### Key information extraction (KIE)

MiniCPM-OCR 1.0 can pull specified fields straight out of an image — for example the store name
and amount on a receipt. Send the image with a field-extraction prompt and ask for a JSON object;
you do not need to produce page Markdown first.

Use the [image recognition API example](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/vllm_deploy_en.md#22-image-recognition) and
replace `Text Recognition:` with:

```text
Extract the "store_name", "amount". Format the output as a JSON object with keys: "store_name", "amount". If an item is not in the image, use "###".
```

Replace both field lists with your own field names (Chinese or English). The response is
model-generated text: parse the JSON and check fields and values before using it downstream.

### Agent skill

Have a coding agent follow the skill to set up the environment, download the model, and parse
a first document:

```text
Read and execute https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/SKILL_en.md
```

### Fine-tuning

[LLaMA-Factory](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/llamafactory_minicpm_ocr_french_en.md) ·
[ms-swift](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/swift_minicpm_ocr_french_en.md) — data preparation, full-parameter SFT with
the multimodal projector frozen, training, and evaluation (French handwritten text lines).

## Quantization

| Field | Value |
| :--- | :--- |
| Method | AWQ (`quant_method: awq`, `version: gemm`, `zero_point: true`) |
| Weight bits | 4 |
| Group size | 128 |
| Activations | BF16 (W4A16) |
| Not quantized | `lm_head`, vision tower, merger, `in_proj_a` / `in_proj_b` |
| Tool | `tc-mb/AutoAWQ` (AutoAWQ fork) |
| Calibration | 234 document-style samples derived from OmniDocBench annotations |

Only the language-model linear layers are quantized. The vision encoder, multimodal projector,
`lm_head`, and the GatedDeltaNet `in_proj_a` / `in_proj_b` projections stay in BF16, so image
encoding is unchanged and recurrent gating is preserved.

Weight footprint drops from about 2.42 GiB (BF16) to about 1.74 GiB.

| File | Notes |
| :--- | :--- |
| `model.safetensors` | 4-bit quantized weights, BF16 vision tower |
| `config.json` | base config + `quantization_config` |
| `tokenizer.json`, `tokenizer_config.json`, `chat_template.jinja` | tokenizer and chat template |
| `preprocessor_config.json`, `processor_config.json` | image preprocessing and processor configs |
| `generation_config.json` | generation defaults

`quantization_config` in `config.json` is what vLLM reads; no extra flag is needed.

## Related checkpoints

| Format | Hugging Face | ModelScope |
| :--- | :--- | :--- |
| BF16 (original) | [🤗](https://huggingface.co/openbmb/MiniCPM-OCR-1.0) | [ModelScope](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0) |
| GGUF (llama.cpp) | [🤗](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-gguf) | [ModelScope](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0-gguf) |
| AWQ W4A16 **(this repo)** | [🤗](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-AWQ) | [ModelScope](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0-AWQ) |
| GPTQ W4A16 | [🤗](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-GPTQ) | [ModelScope](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0-GPTQ) |
| DSpark draft (BF16) | [🤗](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-DSpark) | [ModelScope](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0-DSpark) |
| DSpark draft (GGUF) | [🤗](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-DSpark-gguf) | [ModelScope](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0-DSpark-gguf) |

DSpark **requires a matching main and draft model from the same release** — do not mix draft
weights with a different main checkpoint. See
[DSpark acceleration](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/minicpm_ocr_tutorial_en.md#3-start-the-service).

For OCR quality assessment (auto-accept, human-review routing, best-of-N across models), see
[MiniCPM-OCR Jev](https://huggingface.co/openbmb/MiniCPM-OCR-Jev).

## FAQ

Installation, model downloads, GPU memory, input formats, and unexpected outputs:
[FAQ](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/faq_en.md).

## License

Model weights, code, and documentation are released under the
[Apache License 2.0](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/LICENSE).